An online store wants to know whether a simplified checkout step increases completed purchases rather than merely clicks. Digital experimentation compares controlled variations to estimate whether an intervention changes a chosen outcome. In a basic A/B test, eligible participants are randomly assigned to alternatives and measured consistently. This article gives a practical test-design workflow, not a generic digital-innovation ROI framework. Quantitative examples below are hypothetical and should be adapted to the reader’s actual data.
Key Takeaways
A/B testing compares randomly assigned alternatives against a preselected outcome and hypothesis.
Observed conversion-rate differences are descriptive; uncertainty must be considered before attributing a true effect.
Define sample size planning, experiment duration, and stopping rules before looking at the results.
Track guardrail outcomes and instrumentation quality to detect changes that merely shift harm elsewhere, including refunds and customer complaints.
An inconclusive test can still inform the next experiment when reported without post-hoc success stories or inflated certainty.
An A/B Test Is a Controlled Comparison
A/B testing compares two alternatives—often an existing experience, A, and a proposed change, B—by assigning eligible users to variations and measuring a chosen outcome. The purpose is not simply to see which version receives more clicks. A well-designed experiment estimates whether a change causes an improvement within the tested population, acknowledging sampling uncertainty and possible side effects.
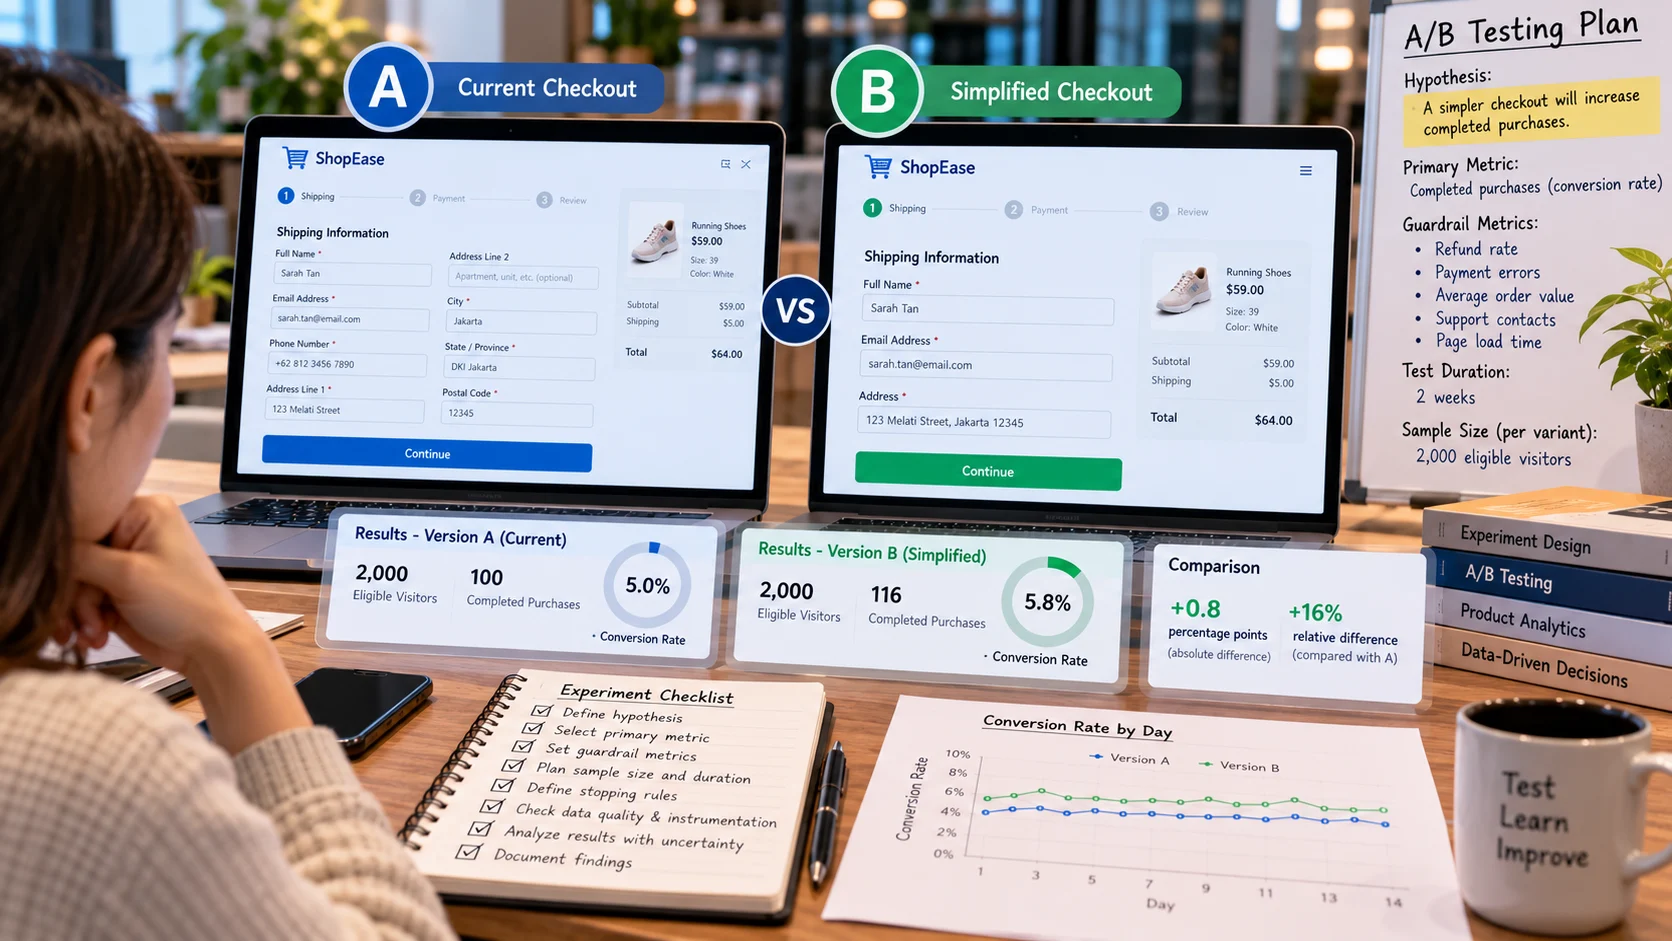
Imagine an online store considering a shorter checkout page. The team believes fewer form fields will increase completed purchases. That is a testable hypothesis. It should specify which users enter the experiment, how assignment works, what counts as a completed purchase, and how long the test will run. Without a clear design, an apparent conversion lift may be caused by seasonality, different traffic sources, or random fluctuations.
Define the Hypothesis and Primary Metric
A useful hypothesis connects an intervention to an expected mechanism: “Removing two unnecessary address fields will reduce checkout friction and increase completed purchases among eligible mobile shoppers.” The primary metric might be completed orders divided by eligible visitors assigned to a variation. This denominator must be identical in meaning across both versions.
Also choose guardrail metrics that detect harmful side effects: refunds, payment errors, order value, support contacts, or page load time. A variation that increases button clicks but also creates more failed payments has not necessarily improved the business outcome. Guardrails prevent teams from declaring victory based on one conveniently positive number.
Decide what to do with repeat visits, users crossing devices, bots, employee traffic, and incomplete purchases. If the same person can switch between A and B on different visits, exposure contamination may undermine the comparison. Persistent assignment and clear eligibility rules help produce interpretable results.
Why Random Assignment Matters
Randomization makes treatment and control groups comparable on average across observed and unobserved characteristics. It does not guarantee that every single experiment yields exactly identical groups; random differences still occur. But systematic assignment, such as putting desktop users into A and mobile users into B, cannot isolate the page change from device differences.
Choose the correct unit of assignment. For a consumer checkout, it might be a customer or browser session, depending on the design. For a workplace team intervention, assigning individual coworkers may create contamination if they influence each other; a team-level design could be more appropriate. The analysis must match the unit and dependence structure used by the experiment.
The experiment should record assignment and exposure consistently. A user who was randomly assigned to B but never saw the new page may matter differently depending on whether the analysis follows assignment or actual exposure. Define this before inspecting results, since changing definitions afterward can bias conclusions.
Calculate an Illustrative Result
Suppose version A receives 2,000 eligible visitors and produces 100 completed purchases. Its conversion rate is 100 / 2,000 = 5.0%. Version B receives 2,000 visitors and produces 116 purchases, giving 116 / 2,000 = 5.8%. The absolute difference is 0.8 percentage points; the relative difference is 16% compared with A.
These arithmetic statements alone do not prove a reliable improvement. The experiment contains sampling uncertainty. A rough standard error for the difference between two independent proportions uses the observed group rates and sample sizes. Here the estimated standard error is about 0.72 percentage points, so the observed 0.8-point difference is not far from what random fluctuation might produce. A simple approximate 95% interval would include zero. Exact interpretation depends on the preselected method and assumptions.
This is a hypothetical teaching example, not a live ByteScope or store experiment. Avoid declaring B the winner merely because 5.8 is larger than 5.0. Review the planned statistical analysis and whether the observed effect is large enough to matter commercially. Even a statistically precise difference may be too small to justify implementation cost.
Sample Size, Duration, and Stopping Rules
An experiment needs enough eligible observations to detect effects that matter. Sample-size planning typically depends on the baseline conversion rate, minimum practically important effect, desired power, and false-positive tolerance. An extremely small expected improvement may require far more traffic than a local business can collect quickly.
Do not stop a test each time the dashboard happens to show a positive significance indicator unless the analysis method explicitly supports sequential decisions. Repeated unplanned checking can inflate false-positive risk. Establish duration or stopping criteria before launch, and account for relevant weekly patterns where practical. Running only during a holiday sale may answer a different question from normal operations.
If traffic is limited, consider testing changes with a strong expected impact, gathering qualitative user feedback, or using smaller-scale usability experiments rather than pretending a tiny A/B test can detect subtle differences reliably.
A Practical Experiment Workflow
Find a real friction point. Use analytics, support tickets, or usability observations to identify a problem worth testing.
Write the hypothesis and mechanism. Explain why the change might affect behavior and what would falsify the expectation.
Select one primary outcome and guardrails. Define event tracking, eligibility, time window, and treatment of missing events.
Choose the assignment unit. Implement randomized, persistent exposure where appropriate and verify that both groups receive the intended version.
Plan sample size and stopping conditions. Define an effect that would justify deployment, not merely the smallest detectable change.
QA instrumentation. Verify conversion events, purchases, cross-device behavior, and error logging before opening traffic.
Run without undocumented changes. Avoid altering pricing, messaging, or eligibility differently across groups during the test.
Analyze according to the plan. Report absolute and relative effects, uncertainty intervals, guardrail changes, and any deviations.
Decide and learn. Ship, iterate, or reject the change based on evidence and practical value; record the experiment so future teams can learn from it.
An experiment should be reproducible enough for someone outside the original team to understand what changed and what evidence supported the decision.
Problems That Make Results Misleading
A sample ratio mismatch occurs when assignment yields an unexpected split beyond reasonable random variation, perhaps due to a logging bug or broken routing. Investigate before interpreting outcomes. Instrumentation errors may double-count a purchase or miss mobile conversions. Multiple unplanned metrics increase the chance of finding a seemingly positive result by accident.
Novelty effects can make a changed interface attractive temporarily; seasonality can alter purchasing patterns; network effects can create interference between groups. Segment analysis can be informative, but repeated post-hoc searching for a winning subgroup is easy to overinterpret. Treat exploratory findings as hypotheses for future tests rather than certified discoveries.
Ethical and Business Boundaries
Not every change is suitable for experimentation. Avoid deliberately exposing people to unsafe, misleading, or unfair treatment merely to increase a metric. Privacy notices and legal obligations still apply. Ensure that experiment assignment does not interfere with access needs or essential services.
In reporting results, distinguish statistical uncertainty from business judgment. Leaders may choose a slightly lower-conversion design because it reduces errors, improves accessibility, or respects user preferences. Experimentation informs decisions; it does not replace accountability.
The habit to cultivate is disciplined learning. Define the problem, measure a meaningful outcome, randomize responsibly, check uncertainty and side effects, then decide based on evidence rather than a dashboard’s green arrow.
Calculating an illustrative A/B test result
Suppose a shop tests a new checkout message. Variant A receives 2,000 eligible visits and 120 purchases; variant B receives 2,000 visits and 150 purchases. Conversion is 6.0% for A and 7.5% for B, an absolute lift of 1.5 percentage points and a relative lift of 25%. Those calculations alone do not establish that B is reliably better. Under a simple independent-binomial approximation, the standard error of the difference is about 0.79 percentage points, so uncertainty remains material.
Variant Visitors Purchases Conversion
A 2,000 120 6.0%
B 2,000 150 7.5%
The example assumes unique independent assignments and complete tracking; real experiments must address repeat users, attribution windows, segment imbalance, and stopping rules. Agree on the primary metric and sample plan before watching the numbers.
What the example teaches. The store randomly shows two checkout designs. A promotion launches halfway through the test, so the analyst checks assignment balance and exposure windows before interpreting conversions. A tiny improvement in clicks is not treated as a win if completed orders or refund rates worsen.
Interpreting Confidence Intervals Without Overclaiming
An uncertainty interval summarizes how much variation a statistical method expects under its assumptions. It does not mean there is a specified probability that a fixed true effect moves randomly inside one already calculated frequentist interval. For practical reporting, explain the range of effects compatible with the data and chosen method, and avoid presenting small positive point estimates as proven benefits when the interval includes no effect or a possible decline.
Business decisions should also consider the minimum worthwhile effect. A checkout change that improves conversion by a fraction of a percentage point may matter at huge scale, but not justify substantial development cost at low traffic. Conversely, a change that reduces payment errors or improves accessibility might be valuable even if a modest A/B test cannot precisely quantify the conversion effect.
Avoiding Data Peeking and Subgroup Stories
Repeatedly checking results and stopping the moment they look favorable can exaggerate evidence if the statistical design does not account for sequential monitoring. Similarly, trying dozens of outcome metrics and user segments after seeing the results can produce attractive patterns by chance. Record exploratory analyses as exploratory, and consider testing promising subgroup hypotheses in a later experiment.
A responsible report documents deviations from the original plan, unexpected traffic anomalies, and the precise metrics used to judge success. Publishing only the most flattering comparison prevents future teams from learning accurately from past trials.
What to Do When the Experiment Is Inconclusive
An inconclusive test is not necessarily a failed project. The result may reveal that the expected effect is too small for available traffic, the change did not address the real obstacle, or the instrumentation needs improvement. Review qualitative feedback, usability recordings collected with appropriate consent, and operational performance. Decide whether to refine the intervention, run a larger appropriately designed test, or stop because the potential benefit is not worth the investment.
An Example of a Result That Is Not Yet a Decision
Suppose variant A records 80 purchases from 2,000 visitors, while variant B records 96 from 2,000. The observed conversion rates are 4.0% and 4.8%, a difference of 0.8 percentage points. That is a real descriptive difference in the sample, but it does not automatically establish that B is better for the population of future visitors. Random variation, audience mix, tracking defects, and how long the test ran all affect what can be concluded.
Do not call the change a win solely because the bar chart is taller. Use the preselected analysis method to quantify uncertainty and check the experiment’s guardrail metrics, such as refund rate or page performance. If the interval around the effect includes meaningful losses, document an inconclusive result rather than rewriting the success criterion after seeing the data.
Frequently Asked Questions
What is the difference between A/B testing and user testing?
A/B testing estimates the effect of controlled variants on measurable outcomes; user testing explores how people experience a design and why they struggle.
How long should an A/B test run?
Long enough to capture representative user cycles and a preplanned analysis window. Ending as soon as a chart looks favorable increases false conclusions.
Can small websites experiment with low traffic?
Yes, but low traffic limits precision. Start with large expected effects, qualitative research, and realistic uncertainty rather than tiny significance claims.
What does a statistically significant result mean?
It means the observed result is unlikely under a specified statistical null model at a chosen threshold. It does not prove business importance or future reproducibility.
Further Reading on ByteScope
Measuring Digital Innovation Value
AI Data Analysis Tools
Sources and Further Reading
NIST: Engineering Statistics Handbook — NIST primary material for frameworks and evaluation methods.
Optimizely: A/B Testing Guide — Industry explanation; corroborate statistical claims.