Privacy risks in artificial intelligence do not end when a company removes names from a training spreadsheet. Some attackers attempt to learn whether a particular person’s record was included in a model’s training data. Others attempt to infer sensitive attributes or reconstruct information from model behavior. These are examples of AI privacy attacks, and they challenge the assumption that publishing a trained model is always safer than releasing the dataset.
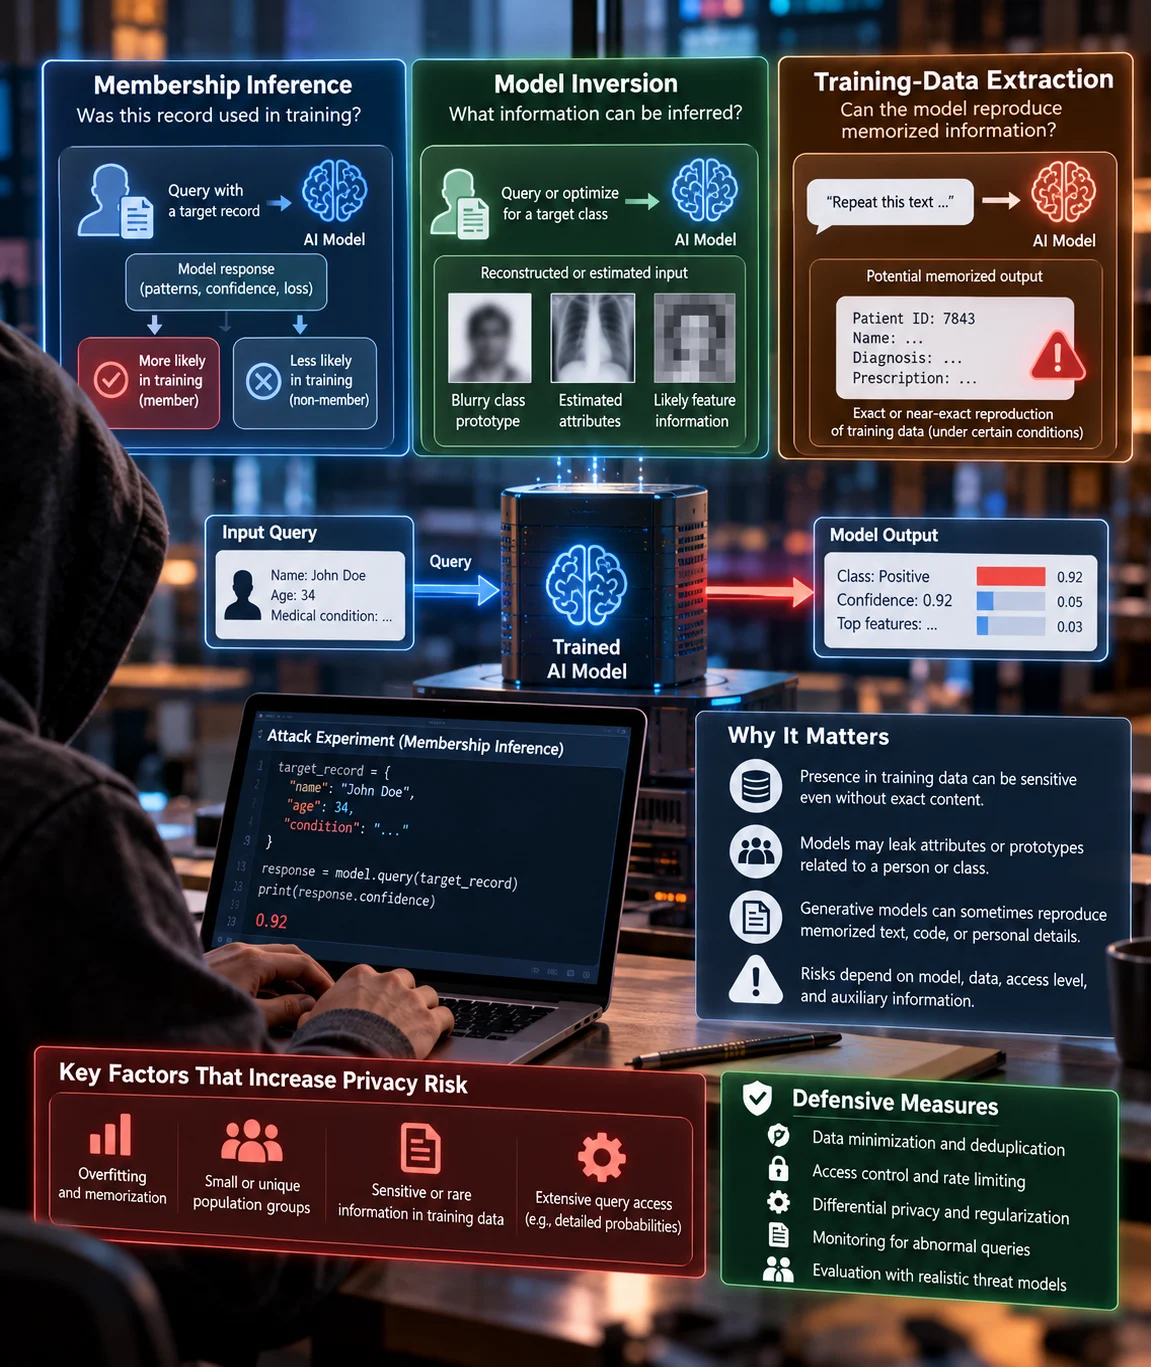
Two often-discussed families are membership inference and model inversion. They are related but not interchangeable. The first asks whether a target record influenced training; the second seeks information about features or representations associated with a class or person. Understanding the differences helps organizations assess exposure without exaggerating what any single experiment proves.
Membership inference: was this record used?
Consider a medical research model trained on records from patients who visited a particular clinic. An attacker knows some details about a person and can query the model. The attacker’s goal is to distinguish whether that person’s record belonged to the training dataset. The model may produce subtly different loss values, confidence patterns, or responses for familiar and unfamiliar examples.
If the mere presence of a record in training is sensitive, such a distinction can violate privacy even if the record’s exact contents are never reconstructed. Membership in a dataset of mental-health treatment, a confidential employee investigation, or another sensitive context can itself be revealing. The risk depends on the model, the interface, the data distribution, and what auxiliary information the attacker already possesses.
Membership inference should not be described as a universally reliable way to identify training records. Attack accuracy can be weak, and apparent success may reflect differences between the sampled member and nonmember populations rather than true training memorization. Evaluate attacks using appropriate baselines, matched populations, and realistic query permissions.
Model inversion: what information can be inferred?
Model inversion refers to attempts to recover or estimate sensitive information about model inputs, features, or representative patterns from access to model outputs and sometimes model parameters. An attack against a classifier might seek an input pattern strongly associated with a target class. Other attacks infer private attributes correlated with a known record.
The output of an inversion attack is not automatically a recovered photograph or exact patient file. It may be a blurry class prototype, a likely attribute, or information that helps an attacker narrow possibilities. Claims of exact recovery should be evaluated carefully: was an original record reconstructed, or was a plausible example generated from a learned distribution?
In practical threat assessment, ask what the attacker gains beyond information already available from public data and general population statistics. A sensitive inference may be possible without model access at all; the security question is whether the model increases the attacker’s ability to learn something they should not know.
Training-data extraction is another distinct risk
Generative models can sometimes reproduce memorized passages, codes, or personal details under particular circumstances. Prompting a model to reveal a memorized text is more appropriately described as training-data extraction than as a generic inversion attack. The methods, evidence, and defenses overlap in places, but the concepts answer different questions.
A model may also reveal private information through a connected retrieval system, log, tool, or incorrectly authorized database query. That is an application security failure even if the underlying model memorized nothing. Threat models should separate learned information from external data exposure rather than treating every leak as the same model property.
The surrounding software architecture therefore matters. A publicly queryable prediction endpoint, a downloadable model with exposed parameters, and a private internal classifier grant different levels of access. Defenses must reflect the actual interface an attacker can reach.
Why overfitting and memorization matter
Models that behave differently on training records than on unrelated examples can create membership signals. Strong overfitting may increase some forms of vulnerability, though low training–test gaps do not prove privacy safety. A model may memorize rare examples or unique strings while achieving normal aggregate test performance.
Large language models trained on diverse text can retain specific sequences that appeared repeatedly or were distinctive in training. Rare but sensitive material deserves extra protection because aggregate utility metrics might not expose the problem. Training-data deduplication, minimization, and careful handling of secrets are valuable before privacy tests even begin.
Privacy risks also depend on group representation. Records from small or unusual populations may behave differently from common examples. Testing only average attack success can miss highly vulnerable subsets. Assess uncertainty and avoid assuming that a defense validated on one dataset applies universally to all populations.
A realistic threat model
Before discussing a defense, describe what the attacker knows and can do. Can the attacker submit arbitrary inputs and view detailed probabilities, or only a binary decision? Can they repeat queries thousands of times? Do they know the architecture, parameters, or training procedure? Can they download the model? Can they obtain records from other sources?
Next describe the protected asset. It might be whether a named person participated in training, the presence of confidential text in a model, or an undisclosed medical attribute. Identify likely harms and legal or organizational constraints. The severity of a privacy attack cannot be inferred solely from a model accuracy number; context and accessibility matter.
A clear threat model also prevents superficial controls. Hiding a web page that exposes model scores may reduce casual access but not protect downloadable model weights. Conversely, a restriction on public query volume may meaningfully limit a black-box attacker with no other access. The safeguard must correspond to the attacker capability.
Reducing exposure before training
The strongest first step is data governance. Use only training records with a legitimate basis, minimize unnecessary identifiers, and avoid storing secrets in free-text fields that later become training examples. Apply retention rules to source files and copies. Evaluate whether less sensitive or aggregated training data can achieve the purpose.
Access control should distinguish data scientists, annotation vendors, model operators, and downstream users. A research model should not automatically inherit broad access to production customer records. Log access to datasets and model artifacts, restrict downloads, and review data-sharing obligations with partners. Removing a name column alone does not make a rich record anonymous if other fields can identify people indirectly.
For tasks where sensitive individual records are not essential, using synthetic or public information may reduce some risks. But synthetic data is not inherently privacy-safe: a generator can memorize its source, and unusual samples may still reveal information. Test privacy properties rather than treating the word “synthetic” as a certification.
Differential privacy and its limits
Differential privacy provides a mathematical framework for limiting how much the output of a randomized mechanism can change when one person’s record is added or removed, under a specified neighboring-dataset definition. Differentially private training methods, such as DP-SGD variants, aim to constrain contributions from individual examples and add carefully calibrated noise during optimization.
A stated privacy parameter is meaningful only alongside the algorithm, accounting method, assumptions, and definition of protected individual. Stronger privacy can require a utility trade-off, especially on small datasets or difficult tasks. Simply adding arbitrary noise to predictions does not automatically provide a useful formal guarantee.
Differential privacy also does not prevent every security failure. It does not fix an application that exposes raw customer documents through an improperly authorized retrieval tool. It does not guarantee fairness or data accuracy, and it does not eliminate the need for careful source governance. Treat it as one component of a broader control system.
Output controls, monitoring, and access boundaries
For prediction APIs, ask whether users need detailed class probabilities or whether a coarser output suffices. Returning fewer details may reduce some attack information, but can also hinder legitimate users and will not stop all attack variants. Rate limiting and monitoring can raise the cost of large-scale probing. Sensitive outputs should be protected with identity-based authorization rather than assuming that difficult-to-guess API URLs are secret.
For generative applications, content filters and refusal policies can limit some accidental disclosures, but should be tested against realistic attacks. Prompts alone are not a reliable data security boundary. When an AI assistant calls a document system, permissions should be enforced by the document system itself. This complements the principles in ByteScope’s AI guardrails guide and responsible AI overview.
Model owners should investigate suspicious query volumes, repeated variations targeting one person’s record, and attempts to extract identifiers. Monitoring must respect privacy as well: keeping every sensitive input forever to detect attacks may create its own unnecessary data exposure.
Designing a privacy evaluation
Choose attack scenarios appropriate to the deployed interface. Construct training-member and nonmember samples carefully, avoiding obvious distribution differences. Evaluate attack success against chance or other relevant baselines, report false-positive rates, and include uncertainty. A privacy study claiming “80% attack accuracy” is difficult to interpret without class balance, available attacker information, and cost of false accusations.
For extraction tests, review whether generated snippets actually match protected data and whether matching text is publicly available. Use approved synthetic canaries or controlled records rather than probing random people’s private data without authorization. Document test permissions and escalation steps. Where possible, employ independent privacy specialists to review high-risk model releases.
Reassess after major changes in training data, model architecture, access rights, or interface capabilities. A private model that later becomes downloadable faces a different threat model. A model deployed behind a new tool-using assistant may expose additional risks even though the original weights did not change.
An example risk register
A small organization can describe concerns without pretending to quantify unknowable risks precisely:
Asset Exposure path Practical control
Membership in sensitive training cohort Repeated prediction queries Limit interface detail; privacy testing; approved access
Memorized confidential strings Generative completion Data minimization; extraction tests; output controls
Private document text Connected retrieval tool Source-system authorization and audit logs
Downloadable model weights Direct parameter inspection Artifact access controls; release review
Risk level should depend on the consequence of disclosure, the availability of the attack surface, and the sensitivity of the underlying information. A row in a risk register is not evidence that an attack is currently feasible.
Mistakes organizations should avoid
First, do not claim a system is private because its model was trained on “anonymized” data without checking reidentification risk. Second, avoid treating a low attack score on one benchmark as permanent proof of safety. Third, do not confuse average memorization risk with protection of unusual or rare records. Fourth, remember that a confidential inference can involve metadata, outputs, or relationships even if no literal training row is recovered.
A further mistake is treating privacy solely as a machine-learning team’s concern. Product interfaces, identity systems, procurement contracts, logging choices, and business retention policies may matter at least as much as the training algorithm. Assign ownership across the full data lifecycle.
Interpreting privacy audit findings without exaggeration
Suppose a membership inference test achieves 60% accuracy on a balanced set of known members and nonmembers, where 50% would be a chance-level baseline. The result may indicate some distinguishability, but it does not mean the attacker can identify every participant or that every data subject has a 60% risk of disclosure. The score depends on sampling, attack knowledge, access, and confidence intervals.
A responsible report separates test conditions from real-world attacker capabilities. It identifies which models and interfaces were evaluated, what additional data the attacker possessed, and which sensitive attribute or membership fact was at stake. If the test used raw confidence vectors that production users never see, deployment exposure could be different. If downloadable model weights are available, the relevant threat model may be much stronger.
Report limitations and unresolved questions openly. Privacy protection depends on the full pipeline, including data collection, training, output interfaces, retrieval, and logging. One benchmark does not certify the system as safe, but it can help prioritize mitigation and ongoing review.
Evaluating exposure without collecting unnecessary secrets
A privacy test need not begin by assembling a large archive of real personal records. Teams can first review access paths, experiment with synthetic or consented evaluation examples, and analyze whether the model returns memorized-looking strings under controlled prompts. Where authorized red-team testing uses sensitive data, the evaluation team should minimize access and retain results only as long as needed. Attack success is also contextual: a model repeating a common public phrase is not equivalent to revealing a rare, private training example. A responsible assessment documents the attacker’s assumed knowledge, the number of queries allowed, the baseline chance of guessing correctly, and the practical consequences of a successful disclosure. This prevents sensational demonstrations from substituting for a measurable understanding of risk.
Frequently asked questions
Can membership inference identify every person in a training dataset?
No. Success depends on the model, access, samples, and assumptions. Many attacks are probabilistic and can produce false positives or weak results.
Does fine-tuning automatically expose private data?
Not automatically, but fine-tuning on sensitive, small, or repetitive datasets can create risks that need testing and governance. Safeguards depend on the actual training and deployment approach.
Is differential privacy sufficient on its own?
No. Its formal protection covers a defined mechanism and threat model. Other exposure paths, including retrieval permissions and logging, still need controls.
A privacy defense should be evaluated against the model’s actual deployment surface. Limiting repeated black-box queries may reduce some attackers’ opportunities, while it provides little protection if trained weights are publicly downloadable. Maintaining this distinction prevents a team from claiming that one operational control addresses every attack type. Keep the threat model current as products and access rules evolve.
Conclusion
AI privacy attacks demonstrate that protecting source files is not the end of protecting personal information. Membership inference, model inversion, and training-data extraction raise distinct questions about what a model may reveal. Begin with a concrete threat model, minimize sensitive training material, test realistic attacker access, and enforce security at every application boundary. Privacy is a system property, not a marketing label attached to a model.
References
Shokri et al.: Membership Inference Attacks against Machine Learning Models
Carlini et al.: Extracting Training Data from Large Language Models