A search box that only matches exact words can miss useful information. Someone searching a support archive for “refund delayed” may need an article titled “Why reimbursement takes several business days.” Vector databases offer one way to find related content by comparing numerical representations of meaning rather than relying exclusively on matching character sequences. They are widely discussed in AI applications, but their value depends on the retrieval problem, data quality, and engineering details.
The important distinction is between generating an embedding and searching it efficiently. An embedding model converts text, images, or other content into a vector; a vector store retains vectors and metadata; a similarity search finds candidates near a query vector. An application still needs access controls, updates, ranking decisions, and a way to check whether retrieved material answers the user’s real question.
What a vector database actually stores
A vector is an ordered collection of numbers. An embedding model maps an input such as a document paragraph into a point in a high-dimensional space. Inputs with similar learned characteristics often lie relatively close together, depending on the model and distance metric. The representation does not contain a perfect, human-readable copy of meaning. It can reflect training biases, ambiguous phrasing, and differences between domains.
A basic retrieval record may include a unique ID, embedding vector, original document or pointer, content type, title, timestamps, source permissions, and other metadata. The vector handles candidate similarity. Metadata handles constraints and application behavior: an internal knowledge base might filter results by tenant, department, document status, or language before showing anything to a user.
Some systems are dedicated vector databases; others are general-purpose databases or search engines with vector indexing capabilities. PostgreSQL with the pgvector extension is one example. The choice is therefore not simply “vector database versus SQL.” You can use a relational database with vector search or combine keyword retrieval and embeddings in a wider search platform.
The search flow, from user query to relevant document
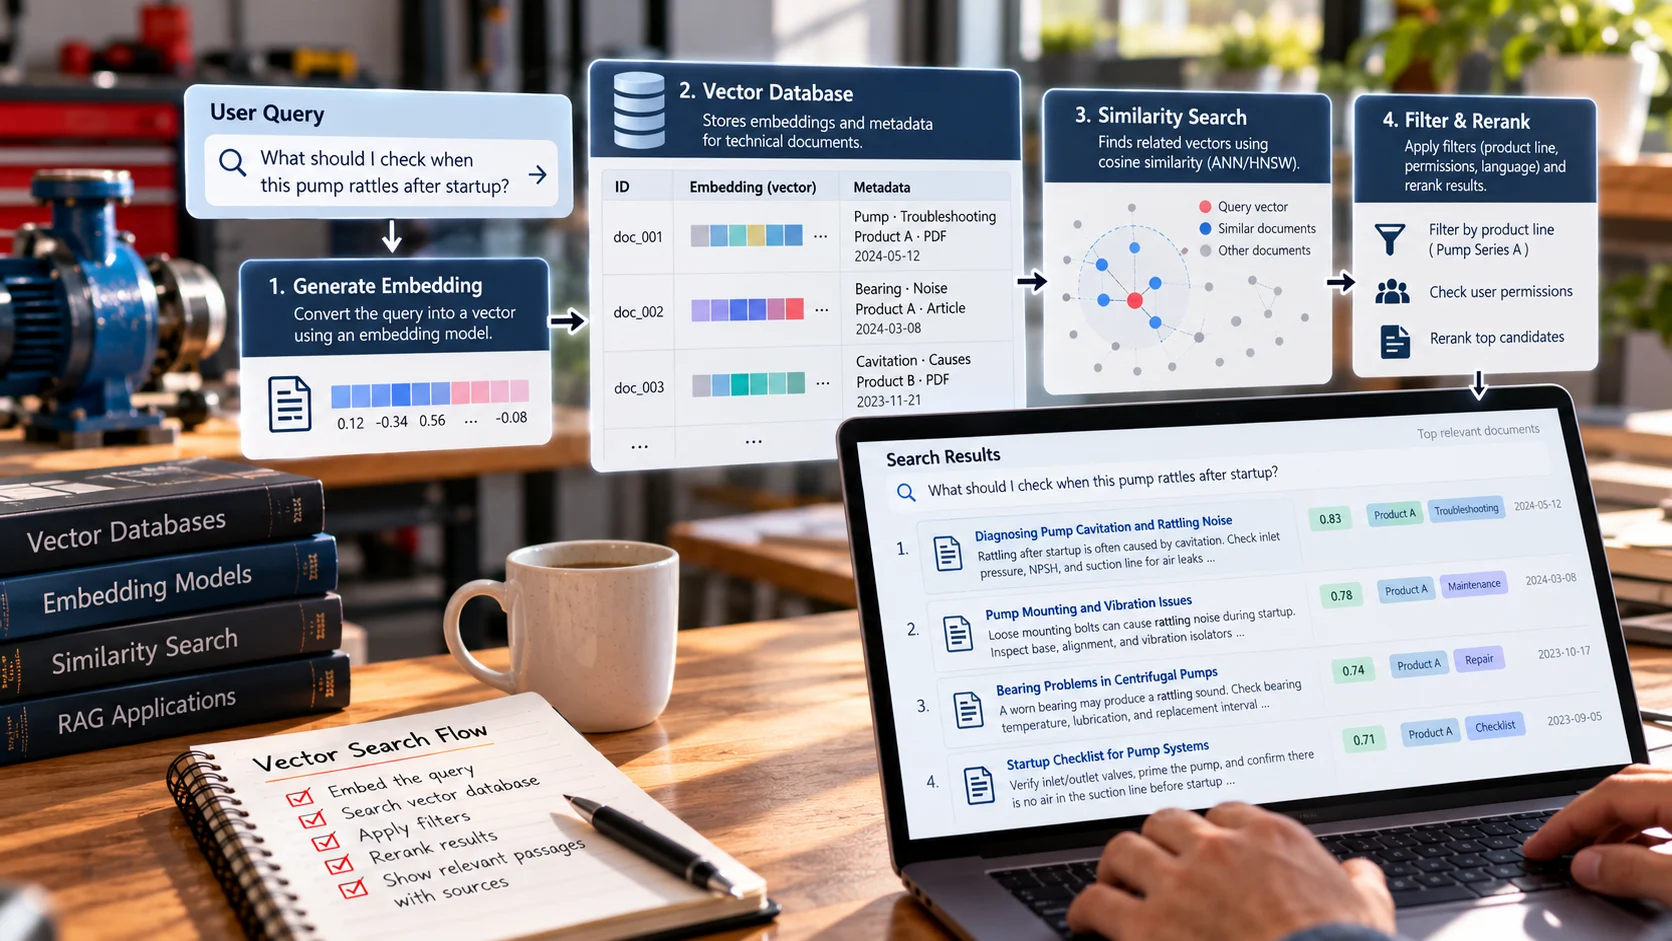
Imagine a repair company with 60,000 troubleshooting notes. A technician enters: “What should I check when this pump rattles after startup?” The system creates a query embedding using the same compatible model or embedding space used for indexed documents. The search engine compares the query with stored embeddings and returns likely matches, perhaps notes about cavitation, mounting, or bearing problems.
The application then filters for the technician’s product line and permission level, reranks candidates if necessary, and presents short relevant passages with source links. If a language model writes a final answer, that is a separate generation step. Retrieval can improve the available evidence, but it does not guarantee the generator will use it correctly.
This division of responsibilities is important. A vector database is not inherently a chatbot, a reasoning engine, or a fact checker. It is infrastructure for finding nearby records under a defined similarity representation. The rest of the system determines whether retrieved candidates are useful and safe to use.
Similarity is a design choice
Common measures include cosine similarity or distance, Euclidean (L2) distance, and inner product. They are related but not interchangeable under all conditions. Cosine measures orientation, largely ignoring magnitude. Euclidean measures geometric distance. Inner product accounts for both direction and magnitude unless vectors are normalized. The embedding model’s documentation should guide metric selection.
Some implementations treat “higher is better”; others return distances where lower is better. Confusing the direction can reverse the ranking. A vector table may also require the index operator class to match the query’s distance operator. For example, pgvector’s HNSW cosine index is configured differently from its L2 index, and a mismatched query may not use the intended index.
In evaluation, similarity scores should not be interpreted as calibrated probabilities that a passage is true or relevant. A cosine similarity of 0.83 is not an 83% probability of correctness. It is a numerical relationship inside a particular representation space. Establish thresholds empirically with real queries, not from an assumed universal meaning of the score.
Exact search versus approximate nearest neighbors
An exact nearest-neighbor search can compare a query against every candidate vector and return the closest matches under the selected metric. It offers straightforward search-quality semantics but becomes costly as datasets and request volumes grow. Approximate nearest-neighbor (ANN) techniques reduce the amount of search work by navigating an index that sacrifices some exactness for speed.
HNSW, or Hierarchical Navigable Small World, is a graph-based method commonly offered by vector search engines. Another approach, IVFFlat, partitions vector space into groups so queries can inspect selected groups rather than all records. Each has tuning parameters, build costs, memory requirements, and recall trade-offs. More aggressive approximation can return results quickly while missing some candidates an exact scan would find.
Think of “recall at 10” as a way to test an approximate index against exact results: for the same set of queries, how many of the true top-ten neighbors appear among the approximate top ten? A high recall at 10 is a useful engineering measure, but users may care more about whether the correct answer appears at the top and is supported by trustworthy documents.
A compact PostgreSQL example
The following SQL illustrates the shape of a vector search with pgvector. The three-dimensional vectors are deliberately tiny for readability; production embedding models usually produce many more dimensions.
CREATE EXTENSION IF NOT EXISTS vector;
CREATE TABLE knowledge_chunks (
id BIGSERIAL PRIMARY KEY,
document_id TEXT NOT NULL,
section_text TEXT NOT NULL,
embedding VECTOR(3) NOT NULL
);
INSERT INTO knowledge_chunks (document_id, section_text, embedding)
VALUES
(‘pump-01’, ‘Check inlet pressure and cavitation.’, ‘[0.1,0.8,0.2]’),
(‘pump-02’, ‘Inspect mount bolts after installation.’, ‘[0.2,0.7,0.1]’);
SELECT document_id, section_text
FROM knowledge_chunks
ORDER BY embedding <=> ‘[0.12,0.78,0.18]’
LIMIT 5;
The <=> operator computes cosine distance in pgvector. This query performs a nearest-neighbor ordering; with a small table, an exact scan may be entirely suitable. After measuring workload characteristics, an operator-matched index could be created:
CREATE INDEX ON knowledge_chunks
USING hnsw (embedding vector_cosine_ops);
Do not interpret the toy vectors as useful embeddings; they are made-up numbers used to demonstrate syntax. A production implementation also needs content ingestion, embedding generation, tenant filters, backup policy, and monitoring.
Chunking decisions determine retrieval quality
Long documents are often divided into passages before embedding. A chunk that is too short may omit the condition that makes a statement meaningful. A chunk that is too long can mix several unrelated concepts, diluting its representation. For a policy manual, preserving headings and sections may be more important than using identical character counts. For a support ticket, the issue, diagnosis, and fix may belong together.
Chunk overlap can reduce the chance of cutting a crucial sentence across boundaries but increases index size and duplicate matches. Store document IDs and offsets so search results can point back to source material. Test retrieval against actual questions, including cases where the same keyword means different things in different departments.
Document updates introduce another challenge. If the policy changes, old chunks should be replaced or versioned in a controlled way. Indexes do not automatically know whether a passage is still approved. Retrieval quality depends on stewardship of the underlying source, not only a good embedding model.
Hybrid search and reranking
Vector similarity is strong at some paraphrase-style matches, but literal search can be better for serial numbers, customer IDs, product codes, and exact phrases. A technical support system may need both. Hybrid retrieval combines keyword and vector candidates, then merges or reranks them. Reciprocal rank fusion is one approach for combining ranked lists without assuming their raw scores are comparable.
A reranker can evaluate the query and a smaller set of candidate passages more deeply than the initial vector search. This can improve relevance but adds latency, compute cost, and another model to monitor. Start by testing the simpler baseline before adopting a complex retrieval pipeline.
A good evaluation set contains realistic queries with known relevant passages. Measure whether those passages are retrieved, their rank, latency at peak load, and how metadata filters affect results. A low-latency search that consistently misses the correct policy is not a successful deployment.
Security: filtering must be enforced, not suggested
A common risk is retrieving private material from the wrong customer or department. An instruction to the language model to “ignore confidential documents” is not an access-control mechanism. Enforce authorization when querying and returning records, and verify the user or service identity at the data access boundary. If the index is shared between tenants, test isolation explicitly.
Metadata filtering interacts with ANN search. Some index implementations apply filters after candidate retrieval; this can produce fewer eligible results than expected. Index design, prefiltering capabilities, and query planning therefore matter to both relevance and reliability. Logs should avoid storing sensitive queries or source passages unless there is a justified purpose and appropriate controls.
Retrieval can also surface malicious instructions embedded in documents. Treat source passages as evidence to be evaluated, not commands for the assistant. Existing ByteScope explanations of AI guardrails and AI agents provide context for enforcing boundaries around downstream model behavior.
Cost and maintenance trade-offs
Consider four cost centers: embedding generation for ingestion and queries, vector storage and index maintenance, search execution, and downstream generation or reranking. Bulk document changes can trigger re-embedding. Switching embedding models may require re-embedding old content because vector spaces are not automatically interchangeable. Memory-heavy indexes can also be expensive even when request volume is modest.
For a small and stable knowledge base, a simple keyword index or exact vector search may be adequate. An elaborate distributed database is not a prerequisite for meaningful semantic retrieval. Choose architecture after measuring dataset size, update frequency, query concurrency, access patterns, and the quality difference between candidate methods.
When vector search is the wrong answer
If a user needs an exact account balance, use the authoritative transactional system, not the closest text passage. If the task is an SQL aggregation over structured records, a properly controlled database query is more dependable than embedding the rows. If decisions depend on legal wording, lexical search and precise citation may be essential even when semantic retrieval helps discover candidate sections.
Vector search should be treated as one tool in the application. It excels at discovering similarity; it does not replace transaction consistency, identity checks, structured queries, or subject-matter review. Overpromising a universal “semantic understanding” layer can hide these responsibilities.
Evaluating retrieval with real information needs
A reliable evaluation dataset should reflect why users search. Include paraphrased questions, exact product identifiers, ambiguous words, obsolete documents, spelling errors, and queries whose answer is absent. For each query, reviewers identify which passages actually contain the needed information. Measure recall at candidate depth, ranking quality, and whether the final application cites the correct source.
For example, “How do I reset the A14 controller after an overheat warning?” needs a specific model procedure. A vector-only search might retrieve general overheating advice while missing the exact A14 manual. A keyword match on the product code and a vector match on “overheat reset” may complement one another. Evaluate the combined retrieval against each approach rather than assuming hybrid is always better.
Include a no-answer test. If the only indexed policy is from 2022 and the query explicitly asks for current rules, a responsible application should say that current evidence was not found rather than cite an obsolete passage as definitive. Metadata about effective dates and approval status often improves outcomes more than another tuning cycle on embedding similarity.
Updating embeddings without breaking search
When changing embedding models, create a migration plan. Model A’s 768-dimensional vectors generally cannot be treated as interchangeable with Model B’s vectors simply because both represent English text. Keep model IDs alongside stored vectors, build a new index, compare retrieval on the same query set, and switch traffic only after testing. Document how the old index will be retired and how re-embedding costs will be controlled. This avoids mixed-space retrieval that looks technically operational but has unreliable rankings.
Frequently asked questions
Do vector databases store the original text?
Some systems do, while others store only vectors and metadata or pointers to content in another service. Retrieval applications commonly retain enough reference information to show a source and enforce access control.
Can I use embeddings generated by two different models in one index?
Not safely as though they occupied the same representation space. Unless compatibility is explicitly established, their dimensions or geometry may differ. Version embeddings and plan migrations rather than silently mixing them.
Is a bigger vector database automatically more accurate?
No. Accuracy depends heavily on source quality, chunking, embeddings, search configuration, filtering, and ranking. Larger storage mainly changes the engineering scale; it does not guarantee more relevant information.
A retrieval design decision is best made with measured workload evidence. Run a representative sample of queries against exact search first, then test ANN indexes only where latency or load justifies them. Preserve relevance judgments and the original query set so each optimization can be evaluated consistently. A faster result is useful only if the correct information remains findable.
Conclusion
Vector databases make it practical to search representations of meaning at scale. To use them responsibly, understand how embeddings are produced, how distance and ANN indexing affect results, and how hybrid search, permissions, document versions, and evaluation complete the workflow. Choose a vector architecture for a demonstrated retrieval problem—not because the application includes AI.
References
pgvector official documentation
PostgreSQL documentation: Indexes