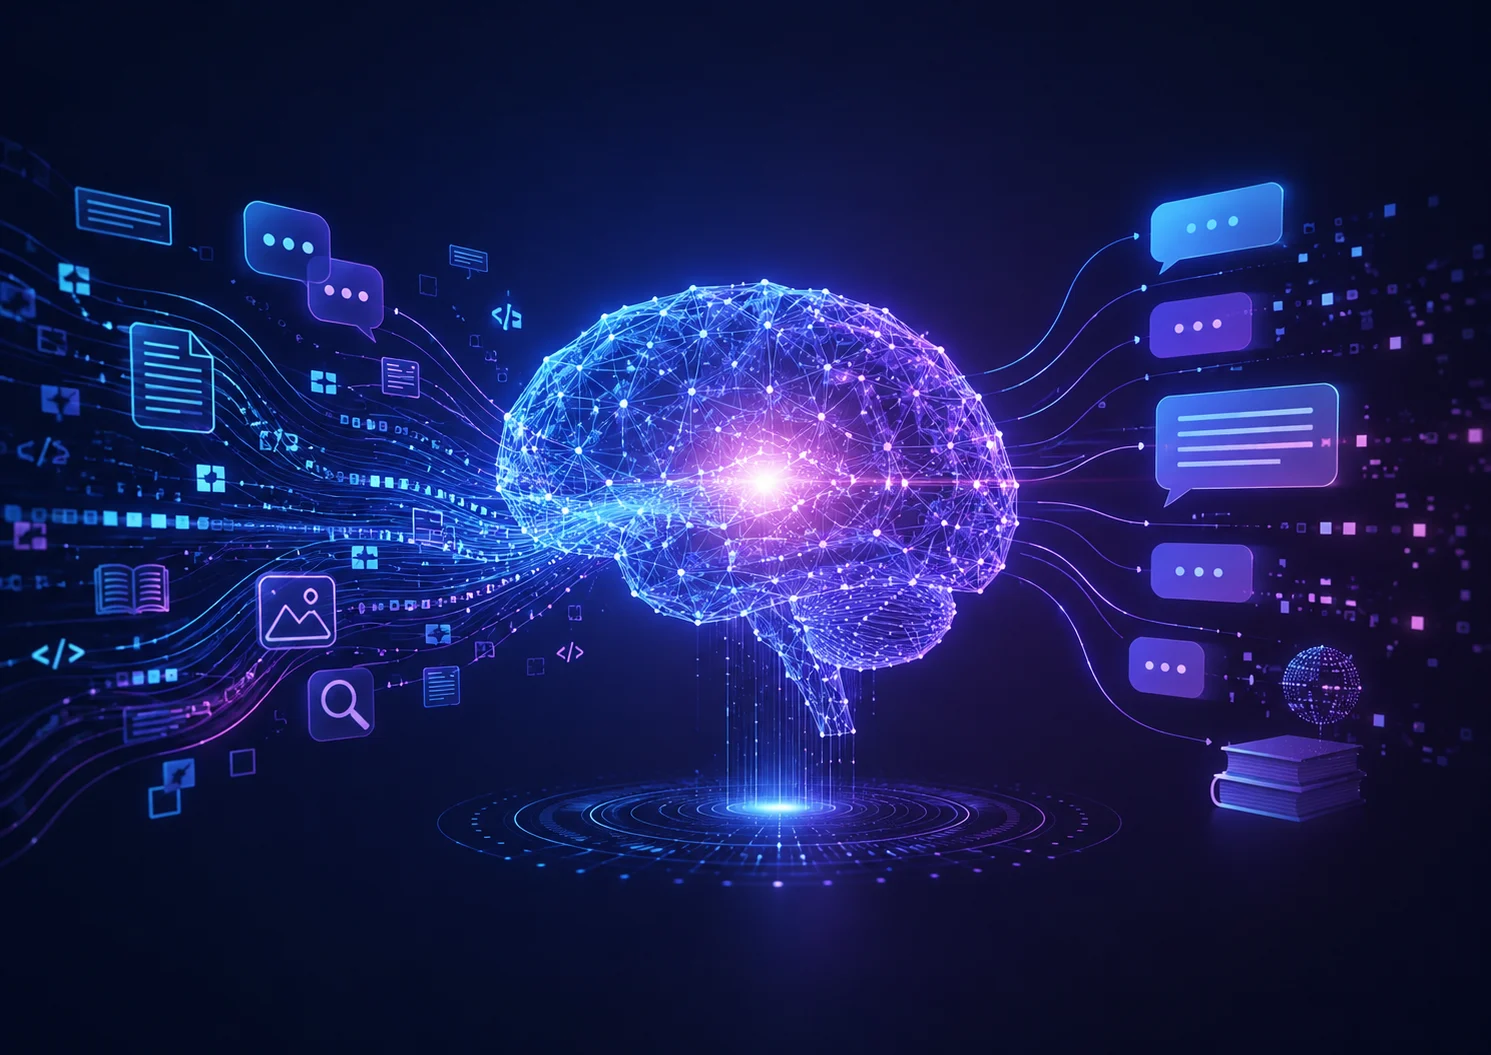
Large Language Models now power many familiar AI experiences, including assistants, search features, writing tools, coding support, and customer service. A Large Language Model, or LLM, is a machine learning model trained on large amounts of text so it can recognize language patterns and generate responses from user input. It can summarize, translate, explain, draft, classify, and answer questions, but fluent output should not be confused with human understanding or awareness. Knowing the basics makes LLMs easier to use effectively and easier to question when their answers are wrong.
What Is a Large Language Model?
The name describes the basic idea. “Language” refers to the model’s focus on human language, while “model” means a computational system trained to recognize patterns and make predictions. “Large” usually reflects the scale of training data, the number of parameters inside the model, and the computing resources needed to train it. Parameters can be imagined as many adjustable settings that training tunes so the model becomes better at identifying relationships in language.
How Large Language Models Learn
During training, an LLM processes enormous amounts of text and learns statistical relationships among words, phrases, sentence structures, and ideas. It does not work like a database that simply stores every sentence and retrieves it later. Instead, training changes the model’s internal parameters so it becomes better at predicting what language is likely to fit a particular context. This pattern learning allows it to generate new language without copying a specific passage.
LLMs process text as tokens rather than exactly as humans read whole words. A token can be a complete word, part of a word, punctuation, or another small unit of text. When producing a response, the model repeatedly predicts the next likely token based on the context it has already processed. Those predictions continue until they form sentences, paragraphs, code, or another type of output.
Transformers, Context Windows, and Prompts
Most modern LLMs rely heavily on transformer architecture. Transformers use a mechanism called attention, which helps the model consider relationships among different parts of the input. In a long sentence, attention can help connect a pronoun with the person or object it refers to even when other words appear between them. This ability to weigh relevant context is one reason transformers work well for summarization, translation, question answering, coding assistance, and conversation. Beginners do not need the mathematics behind attention to understand its purpose: it helps the model identify which information matters while processing language.
Every LLM also has a context window, which is the amount of tokenized information it can consider at one time. That context may include the current prompt, earlier conversation, reference material, or documents supplied to the system. Larger context windows can help with long reports or extended conversations, although they do not guarantee that every detail will be handled equally well. Prompts guide what the model does by providing a question, task, constraints, examples, or background information. Clear and relevant prompts usually produce more useful responses than vague ones, while simply making a prompt longer does not guarantee a better answer.
How LLMs Are Trained
Most LLM development begins with large-scale pretraining, where the model learns broad language patterns from substantial datasets using significant computing resources. Developers may then use additional methods to improve usefulness or align the system with preferred behavior, including fine-tuning on curated examples and techniques that incorporate human feedback. The exact process differs across models, and not every LLM is trained in the same way. Training can improve reliability and task performance, but it does not turn a model into a guaranteed source of facts. What an LLM can do depends on its training, design, available context, and how it is deployed.
What Large Language Models Can Do
Because LLMs are built around language and context, they can support many practical tasks. They can draft and rewrite text, summarize documents, translate content, answer questions, brainstorm ideas, classify information, explain code, and assist with software development. In education, they may explain a difficult concept; in business, they can organize reports or draft routine communication; in customer service, they can assist agents with common requests. Researchers, marketers, writers, and developers can also use them to explore or restructure information. These applications are generally most useful when the model supports a human workflow rather than replacing review and judgment.
Large Language Models are part of the broader field of Generative AI, but the terms are not interchangeable. LLMs focus primarily on language, while Generative AI also includes systems that can create images, audio, video, music, and other content. Some AI systems are multimodal, meaning they can work with more than one type of input or output, such as text and images. Understanding this distinction helps beginners place LLMs within the larger AI ecosystem.
Limitations, Privacy, and Responsible Use
Fluent responses can make an LLM sound more certain than it should. Models can generate incorrect information, invent details, reflect bias, misunderstand vague instructions, or rely on knowledge that is incomplete or outdated. Fabricated or unsupported claims are commonly called hallucinations, showing why polished wording is not the same as factual accuracy. Context limits can also affect performance on long or complicated tasks. For important information, users should verify critical claims with trustworthy sources rather than assuming an LLM response is automatically correct.
Privacy deserves similar attention. Users should be cautious about entering confidential documents, personal data, private business information, or other sensitive material unless they understand how the service handles that data. Privacy policies, retention practices, and business controls differ between providers and products. Effective use combines clear instructions with careful review: provide relevant context, define the goal, inspect the response, refine the prompt when necessary, and verify important details. The model can accelerate work, but responsibility for the final decision still belongs to the user.
The Future of Large Language Models
LLMs are likely to become more deeply integrated into software, productivity tools, search systems, and specialized professional applications. Future improvements may include longer context, stronger multimodal capabilities, better tool use, more specialized models, and greater reliability. These developments could make AI assistants more useful for working with information and software, but they do not remove the need for human expertise. People still need to frame problems, judge whether an answer makes sense, and apply results appropriately. The most useful role for LLMs is likely to remain collaborative rather than simply replacing human decision-making.
Conclusion
Large Language Models matter because they can process language, recognize complex patterns, and generate useful responses across many tasks. Their abilities come from large-scale training, token-based processing, transformers, contextual prediction, and alignment rather than human-like consciousness or perfect knowledge. Used carefully, they can help people write, analyze, summarize, code, learn, and organize information more efficiently. Used uncritically, the same fluency can hide factual errors, bias, privacy risks, or misplaced confidence. Understanding how LLMs work and where their limits remain gives users a stronger foundation for using them effectively and responsibly.