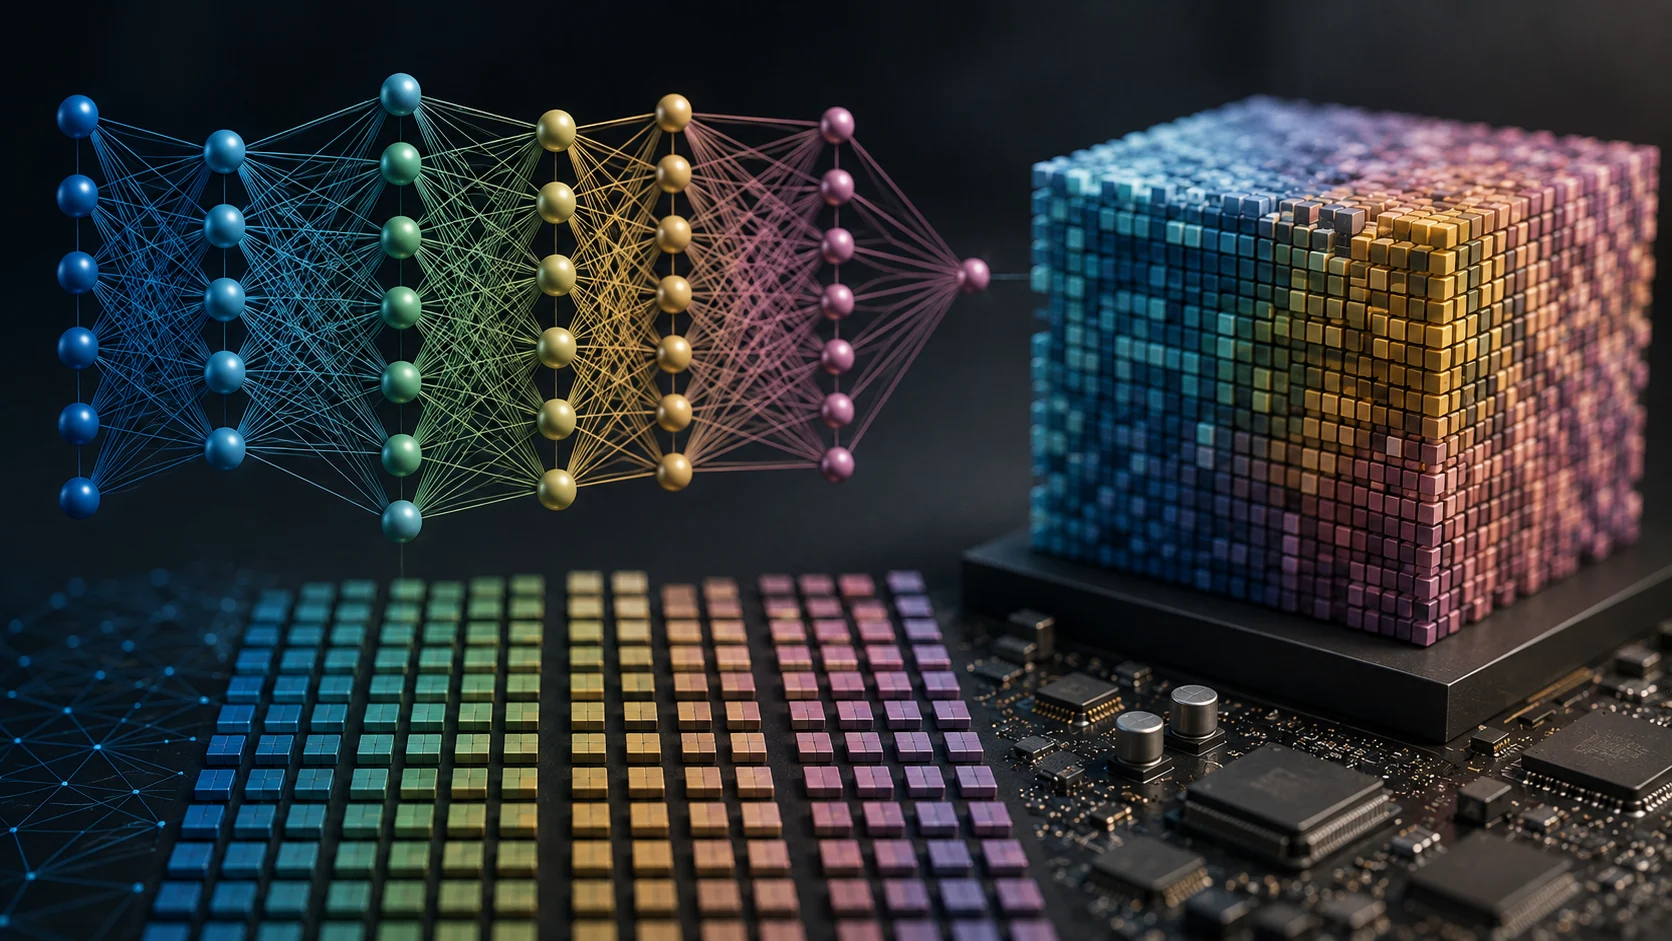
AI model announcements often include phrases such as “7 billion parameters,” “30 billion parameters,” or even much larger numbers. Those figures sound impressive, but what exactly is a parameter, and what does parameter count tell you about a model?
Parameters are the learned numerical values inside a model. Training changes these values so the network becomes better at producing useful outputs from its inputs.
What Is a Model Parameter?
A neural network contains many mathematical operations connected through layers. Parameters are values, often called weights and biases, that influence how signals move through those operations.
At the start of training, many of these values are initialized without useful task knowledge. Training repeatedly adjusts them based on errors between the model’s predictions and desired outcomes.
After enough training, the collective pattern of parameters encodes capabilities learned from the data.
Why Are There So Many Parameters?
Modern language and multimodal models need to represent an enormous variety of patterns. Language includes grammar, facts, styles, relationships, code structures, and many kinds of reasoning behavior.
A large number of parameters gives the network more capacity to represent complex functions. But capacity alone is not enough. The model also needs suitable architecture, training data, optimization, and evaluation.
Parameter Count Is Not the Same as Knowledge
It is tempting to imagine each parameter as storing a specific fact. That is not how neural networks work. Information is distributed across many weights and activations.
A single parameter does not normally correspond to “the capital of France” or one grammar rule. Model behavior emerges from interactions across large numbers of parameters.
Does a Bigger Model Always Perform Better?
No. Larger models often have more capacity, but performance depends on much more than size. A smaller model with strong data, architecture, and training can outperform a larger model on a specific task.
Models can also be specialized through fine-tuning, distillation, retrieval, or tool use. These techniques can improve application performance without simply increasing the number of parameters.
Parameters Affect Memory and Hardware Requirements
Model weights must be stored somewhere. More parameters generally require more memory, although the exact amount depends on numerical precision and architecture.
This affects whether a model can run on a phone, laptop, workstation, or only on powerful servers. Quantization can reduce the memory required to store each parameter, making local deployment more practical.
This tradeoff is central to small language models.
Dense Models and Mixture-of-Experts
Parameter count can become misleading when comparing different architectures. In a dense model, most parameters may participate in each inference step.
A mixture-of-experts model can contain a much larger total parameter count while activating only a subset of specialized components for each token or request.
This means two models with similar total parameter counts can have very different computational requirements.
Active Parameters vs. Total Parameters
For architectures that route inputs through selected experts, the number of active parameters can matter more for inference cost than the total stored parameters.
When evaluating model specifications, developers should therefore look beyond one headline number and consider architecture, memory use, throughput, latency, and benchmark results.
Parameters and Training Data
A large model trained on poor data will not automatically become useful. Parameters learn whatever statistical patterns the training process exposes them to.
Data quality, diversity, curation, and objective design strongly influence what the model learns. Our guide to AI training data explores this relationship further.
Parameters Are Different From Hyperparameters
Parameters are learned during training. Hyperparameters are settings chosen by developers, such as learning rate, batch size, number of training steps, model architecture, or generation controls.
The distinction matters because hyperparameters shape the training process, while parameters are the values produced by that process.
Why Parameter Counts Became a Popular Metric
Parameter count is easy to communicate and gives a rough sense of model scale. It was therefore widely used as a shorthand for model size.
As architectures have diversified, the number has become less useful as a standalone measure. Modern model comparisons increasingly need to consider quality, efficiency, context length, multimodality, tool use, reasoning behavior, and deployment requirements.
The Bottom Line
AI model parameters are learned numerical values that determine how a neural network transforms inputs into outputs. Large models can contain billions of parameters because complex tasks require substantial representational capacity.
Parameter count is useful for understanding scale, but it is not a direct measure of intelligence or quality. The best model for a task depends on the entire system: architecture, data, training, inference efficiency, context, tools, and evaluation.
A Practical Checklist Before You Rely on Model Parameters
Define the job first. Decide what success means before choosing a model or product. A system can look impressive in a demo while solving the wrong problem. Write down the expected output, the information it may use, the acceptable error rate, and which decisions still require a person.
Test representative examples. A useful first test is to compare models using real quality, latency, memory, and task performance rather than parameter count alone. Include normal cases and difficult edge cases. The goal is to learn where the system is dependable and where it needs stronger instructions, additional tools, or human review.
Verify important outputs. Do not confuse fluency with correctness. Check facts, calculations, citations, permissions, and important transformations against a reliable source. The more expensive or difficult an error would be to reverse, the stronger the verification process should be.
Review privacy and access. Understand what information is being sent to the system, where it is stored, and who can retrieve it later. Give connected AI tools only the permissions they need. Sensitive data should follow the same governance rules that apply elsewhere in the organization.
Measure value over time. Track time saved, correction rate, reliability, user satisfaction, and operational cost. A tool that feels fast during the first week may not create lasting value if people spend the same amount of time fixing its output.
Common Mistakes to Avoid
One common mistake is choosing technology before defining the workflow. Another is testing only ideal examples. Teams also tend to add automation without planning what happens when the model is uncertain, the data is missing, or a connected service fails.
The most important limitation to keep in mind is that parameter count says little by itself about architecture, training quality, active computation, or real application performance. Build the workflow around that reality rather than assuming future model improvements will automatically solve it.
Frequently Asked Questions
Is model parameters always more accurate than a simpler approach?
No. AI is valuable when the task benefits from language understanding, pattern recognition, generation, or flexible decision support. A deterministic rule, database query, spreadsheet formula, or conventional software function can be better when the task is predictable and exact.
Do I need to understand the mathematics behind model parameters?
No. A conceptual understanding is enough for most users and product decisions. Mathematics becomes more important when you are implementing, optimizing, or researching model parameters at a technical level. Start with the purpose, inputs, outputs, tradeoffs, and failure modes before going deeper into equations.
What is the safest way to start using model parameters?
Begin with a narrow, reversible use case. Keep source material or original data available, review the output manually, and document the situations where the system fails. Expand automation only after the workflow performs consistently on representative examples and users know how to recover when it is wrong.