Large language models can require more memory and computing capacity than a laptop, phone, or small server can comfortably provide. One way to make them more practical is model quantization: representing some of the model’s numerical values with fewer bits. A quantized model may occupy less space and sometimes execute more efficiently, but smaller files do not automatically mean faster or equally accurate predictions.
The outcome depends on which values are quantized, the precision used, the model architecture, the inference engine, and the device running it. A four-bit model that fits into memory may still be slow if its hardware lacks efficient kernels. A compressed model can also perform well on casual chat while struggling with the exact domain-specific task for which it was chosen.
This article explains how quantization works, uses a simple memory calculation, compares common approaches, and provides a practical evaluation method for people considering a local or lower-cost AI deployment.
Key Takeaways
Quantization reduces numerical precision for weights, activations, or other values, depending on the method.
Lower-bit representation can save memory, but runtime memory also includes buffers, activations, and the attention cache.
Post-training quantization differs from quantization-aware training; neither should be confused with knowledge distillation.
Speed benefits depend on hardware support and implementation, not only checkpoint size.
Compare quantized alternatives on your own tasks, target hardware, and realistic input lengths.
What Is AI Model Quantization?
Modern neural networks store many numerical parameters, often called weights. These values influence how information passes through the network. Training adjusts them to minimize errors on an objective. During inference, the model uses the learned values to process new inputs and generate predictions or text.
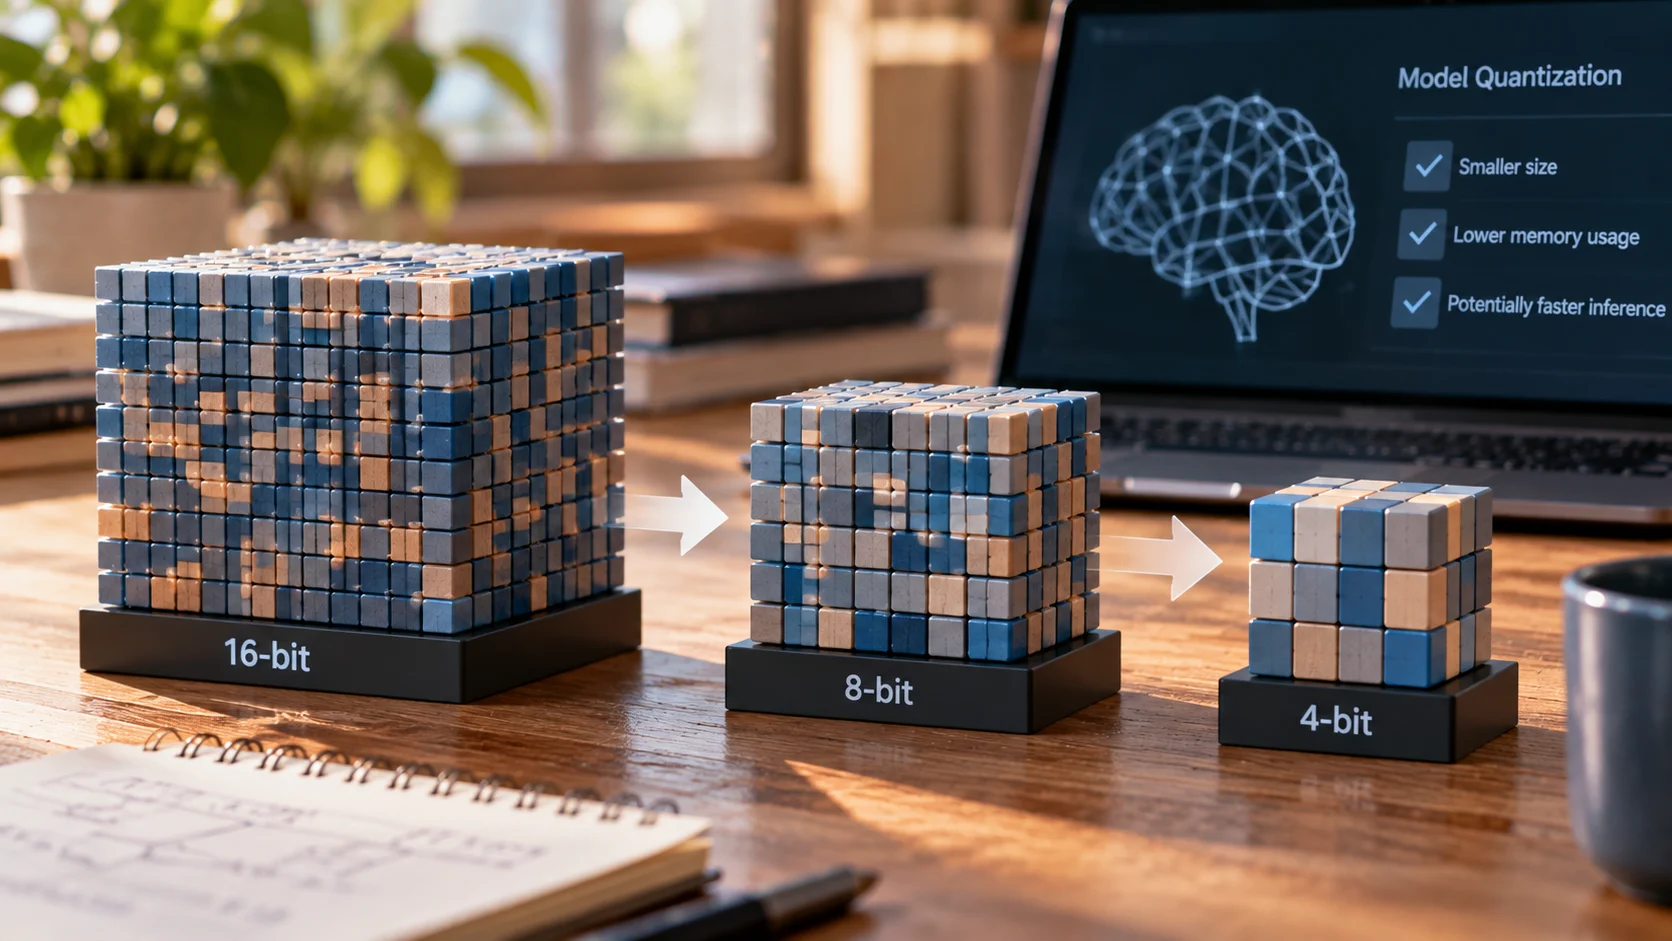
A conventional representation may store weights using 16-bit floating point numbers. Quantization replaces some numerical values with a smaller representation, such as eight-bit or four-bit values, along with information needed to interpret or scale them. This can substantially reduce weight storage.
The process is not simply deleting every second bit. Quantization algorithms map numbers into a restricted set of representable values, often with scales and other metadata. The approximation introduces numerical error, and a good method attempts to keep that error from damaging the model’s useful behavior too much.
Some systems quantize only weights, others also quantize activations or intermediate computations, and some use mixed precision so sensitive parts of a model retain a higher numerical format. That is why two models both described as “4-bit” may have different file sizes, memory needs, and output quality.
Understanding Floating-Point and Lower-Bit Formats
A floating-point value represents numbers with a sign, exponent, and fraction according to a chosen format. Common AI computation formats include 32-bit and 16-bit variants. Integer-like quantized representations encode values into a smaller discrete range plus scaling information.
When eight-bit values replace sixteen-bit values for the same set of weights, raw weight storage may be roughly halved. Four-bit values may reduce the raw storage even further. Yet real checkpoints can store some layers at higher precision, use additional metadata, and reserve memory for computation. You cannot infer actual GPU requirements from weight arithmetic alone.
Precision is an engineering choice, not a quality badge. A small classification network and a very large conversational model can respond differently to the same nominal format. The correct question is which numerical approximation retains the behavior the application needs.
A Simple Memory Example: Seven Billion Parameters
Consider a hypothetical model with seven billion parameters. Ignoring all non-weight memory, basic arithmetic gives:
Weight representation Approximate raw weight storage
16-bit 14 GB
8-bit 7 GB
4-bit 3.5 GB
The calculation is straightforward: multiply the number of parameters by the bits used per weight, then convert the result to bytes. These figures are approximate decimal gigabytes and are not complete deployment specifications.
At runtime, an inference system also needs space for model metadata, temporary activations, buffers, framework overhead, and the key-value cache used by transformer attention. Context length and concurrent requests can increase memory demand substantially. Some quantized formats also require scale factors or other extra values. A model with roughly 3.5 GB of raw four-bit weights should therefore not be advertised as guaranteed to run in exactly 3.5 GB of RAM.
This distinction matters when choosing a laptop or rented server. A model that narrowly fits at startup may run out of memory once the prompt becomes long or several users connect simultaneously.
Post-Training Quantization Versus Quantization-Aware Training
Post-training quantization converts an already trained model to a lower-precision representation. It can be attractive because it avoids repeating the complete original training process. Some techniques use calibration examples to identify numerical ranges or sensitivity; others use specialized optimization methods to reduce the impact on important weights.
Quantization-aware training exposes a network to the effects of reduced precision during training or fine-tuning. The model can adjust its parameters to cope with rounding and representational limits. This may protect accuracy, but it requires additional training effort and depends on compatible algorithms and tooling.
Neither approach guarantees identical outputs compared with the original model. Quantization changes numerical computation, and small changes can propagate through a generative model’s token probabilities. The size and consequences of those changes must be measured for the actual application.
Why a Smaller Model May Not Run Faster
Memory and throughput are related but different constraints. Quantization can reduce the number of bytes moved between memory and processors. This can help workloads limited by memory bandwidth. But some devices lack efficient support for the selected operations and may need extra conversions or dequantization steps.
A four-bit model can be slower than an eight-bit one on hardware whose optimized kernels favor the higher format. Batch size, context length, decoding strategy, runtime library, and CPU or GPU characteristics can also change the ranking.
Do not use a vendor’s benchmark from a different device as definitive evidence. Measure time to first token, tokens per second, peak memory, and end-to-end response time on the same hardware and workload. If a tool’s interface adds retrieval, network calls, or post-processing, include those costs too.
Quality Can Change in Uneven Ways
Compression may preserve simple conversational responses while damaging more delicate abilities. Exact data extraction, multilingual text, structured output, code generation, and long-context reasoning may not deteriorate uniformly. A model that still produces pleasant prose can nevertheless become less reliable for a specific business workflow.
Use a task-focused evaluation set containing ordinary inputs and difficult edge cases. If you are building a customer-support assistant, test policy citations, ambiguous questions, and cases requiring escalation. For a local coding assistant, test whether generated code executes and passes the expected tests rather than rating style alone.
Compare the quantized model with its unquantized baseline under equivalent prompts and decoding settings. Differences in instruction templates or tokenizers can overwhelm the effect you are trying to measure. Store model and runtime versions so later experiments remain interpretable.
A Practical Workflow for Choosing Quantization
1. Define the deployment constraint
Identify what problem quantization is intended to solve: not enough GPU memory, high inference cost, poor latency, limited power, or a requirement to process information locally. Write down the device, available RAM or accelerator memory, expected concurrent users, and typical prompt length. Without a concrete constraint, “smaller” is not a meaningful success criterion.
2. Establish a baseline before compressing
Run the original model, or the closest supported reference configuration, on a representative task set. Record output quality and any hardware limitations. If the full model cannot run on the target device, use a controlled reference environment and document the difference. Evaluate the actual task, not only generic knowledge questions.
3. Choose candidate formats and runtimes
Select supported eight-bit, four-bit, or mixed-precision formats appropriate to the hardware. Check compatibility with the model architecture, framework, and available inference kernels. A convenient checkpoint may not support all required operators or context features.
4. Compare outputs and resource use
Keep prompts and test criteria stable. Measure peak memory, warm and cold startup behavior, time to first token, throughput, and error rates on the same sample. Include long prompts if real users will submit them, because memory pressure and attention costs can differ significantly from short demos.
5. Review failures by category
Do not accept a single average score as the whole story. Look for regressions in tasks where precision matters: identifiers, small numerical differences, unusual language, and format constraints. Decide whether those failures are acceptable for the use case or whether another precision level is necessary.
6. Deploy with monitoring and a fallback
Record model files, format, runtime, configuration, and quality results. Monitor whether real workload patterns differ from the evaluation. Preserve an operational fallback if the compressed model becomes too slow or produces errors that the organization cannot tolerate.
Choosing Calibration Data and Understanding Outliers
Calibration is often discussed as if it were a routine conversion step, but the selection of examples can determine whether a low-precision model is useful. Imagine an assistant expected to summarize Indonesian supplier invoices. If its calibration or representative evaluation inputs contain only short English conversations, they may fail to expose difficulties with invoice tables, currency symbols, scanned text, and mixed-language descriptions. A model can therefore look stable in a general demonstration while losing reliability on the organization’s documents.
Quantization methods vary in what they measure. Some estimate activation ranges using sample inputs; some optimize groups of weights; others apply more advanced corrections. The role of calibration depends on the particular algorithm, and it is inaccurate to assume that every quantized format requires the same dataset. The practical rule is to study the method’s documentation and use representative, legally permitted examples where relevant.
Numerical outliers also matter. Most values in a tensor may sit within a narrow range while a few have unusually large magnitude. A crude uniform mapping that covers the outliers can leave relatively few useful representable levels for ordinary values. Methods using smaller groups, selective higher precision, or more careful scaling can reduce this problem, although they may increase metadata, complexity, or processing cost.
Comparing Quantized Checkpoints Fairly
A comparison is only meaningful if the configurations are described precisely. Record the model identifier, tokenizer revision, context size, quantization method, runtime, hardware, batch size, and decoding parameters. Set the same stopping rules and maximum output lengths. Warm up each model before measuring sustained token throughput, but also record cold-start time if the service starts on demand.
For a hypothetical trial, suppose an eight-bit configuration completes an extraction task in 4.2 seconds at a 98% validated-field accuracy rate, while a four-bit configuration takes 3.4 seconds but drops to 91%. The percentages and timings are illustrative, not product benchmarks. If the errors involve invoice payment amounts, a 0.8-second saving may be unacceptable; if the task is drafting disposable brainstorming notes, the trade-off could be reasonable. The business context determines the tolerance, not the compression ratio alone.
Finally, separate cost per generated token from cost per successful task. A model that is inexpensive per token may become costly if staff must frequently review, rerun, or correct its results. The total workflow—including quality control—should be the unit of comparison.
Quantization Is Not Knowledge Distillation
These techniques are sometimes grouped together under model compression, but they work differently. Quantization changes the numerical representation of an existing model. Knowledge distillation trains a student model to imitate useful behavior from a teacher model, potentially reducing architecture size or parameter count.
A student can itself be quantized, so the methods are not mutually exclusive. But neither should be confused with pruning, which removes selected weights, connections, or structures. The right technique depends on whether your limiting factor is raw memory, execution speed, model size, deployment environment, or task quality.
Four Common Mistakes
Assuming memory arithmetic equals runtime memory. Raw weight size excludes several important allocations. Confirm actual peak consumption under realistic context and concurrency.
Assuming four-bit always beats eight-bit. Hardware and kernels determine whether lower precision translates into faster useful work. Benchmark both where possible.
Evaluating only simple prompts. Compression errors can be concentrated in difficult cases. Include the real business task, representative edge cases, and any accuracy constraints.
Ignoring model and format compatibility. A downloadable quantized model is not automatically supported by every inference engine. Verify architecture compatibility, license conditions, and tooling before deployment.
Frequently Asked Questions
Does quantization retrain the original model?
Not necessarily. Post-training methods operate on an existing model, while quantization-aware approaches incorporate quantization effects into training or fine-tuning.
Does an INT4 model always use half the memory of INT8?
Its raw weight bits may be approximately half, but runtime memory includes scaling metadata, cache, buffers, and sometimes higher-precision layers. Real usage must be measured.
Can quantization change the answers a model gives?
Yes. Numerical approximation can affect output probabilities and sometimes task accuracy. The effect varies by model, format, workload, and implementation.
Should a beginner start with the smallest quantized model?
Not automatically. Start with the task and available hardware, choose a compatible model, and compare a few formats on representative examples. A slightly larger model may provide a substantially better experience.
Conclusion
AI quantization can make trained models easier to deploy by reducing the precision needed to represent some of their values. It is an important optimization, but not a universal shortcut to better speed or identical accuracy. Evaluate weight memory, full runtime demands, throughput, and task-specific quality together. The best quantized model is not simply the smallest file; it is the configuration that performs the intended job reliably on the hardware you actually have.
Further Reading on ByteScope
Small Language Models Explained
AI Model Parameters Explained
AI Inference Explained
Sources and Further Reading
Hugging Face: Quantization Overview
PyTorch: Quantization Documentation
Memory examples are simplified calculations, not measured device benchmarks.