Ask the same language model to draft a product headline twice, and you may receive two different sentences. That variation is not necessarily an error. Generative language models produce text by predicting a distribution of possible next tokens and selecting from that distribution. Two commonly discussed controls—temperature and top-p—change how those selections are made.
These settings are often described as creativity controls. That shorthand is convenient but incomplete. They change sampling behavior; they do not provide new knowledge, verify an external fact, repair a confusing instruction, or guarantee an original idea. Understanding the distinction helps you choose settings that suit a particular task and test their effects fairly.
This guide explains the mechanics without requiring advanced mathematics, includes a small probability example, and shows how to evaluate sampling settings for structured extraction, business writing, and brainstorming.
Key Takeaways
Temperature changes how concentrated the next-token probabilities are before selection.
Top-p, also called nucleus sampling, limits choices to a set of tokens covering a specified cumulative probability mass.
Lower temperature often produces more predictable wording, but it does not guarantee factual correctness.
Model versions, prompts, external context, provider defaults, and execution details all affect reproducibility.
Test one sampling parameter at a time on several representative tasks, rather than copying a universal setting from social media.
Why Does the Same Prompt Produce Different Answers?
A language model does not normally retrieve one fixed sentence corresponding to an input. At each generation step, it assigns scores to possible next tokens. A token may be a whole word, part of a word, punctuation, or another unit used by the model. The scores are transformed into probabilities; a decoding method then selects the next token.
The choice influences later steps because the model continues with the text it has already generated. Selecting a slightly different phrase near the beginning can lead to a substantially different paragraph. This is why two outputs can express similar ideas in different words even though they began with the same prompt.
Some applications use more deterministic decoding, while others use sampling to encourage variation. Providers also make different settings available. A setting that works with one model is not a promise about another model’s behavior, especially when the underlying model or service implementation changes.
Temperature: Changing the Shape of the Distribution
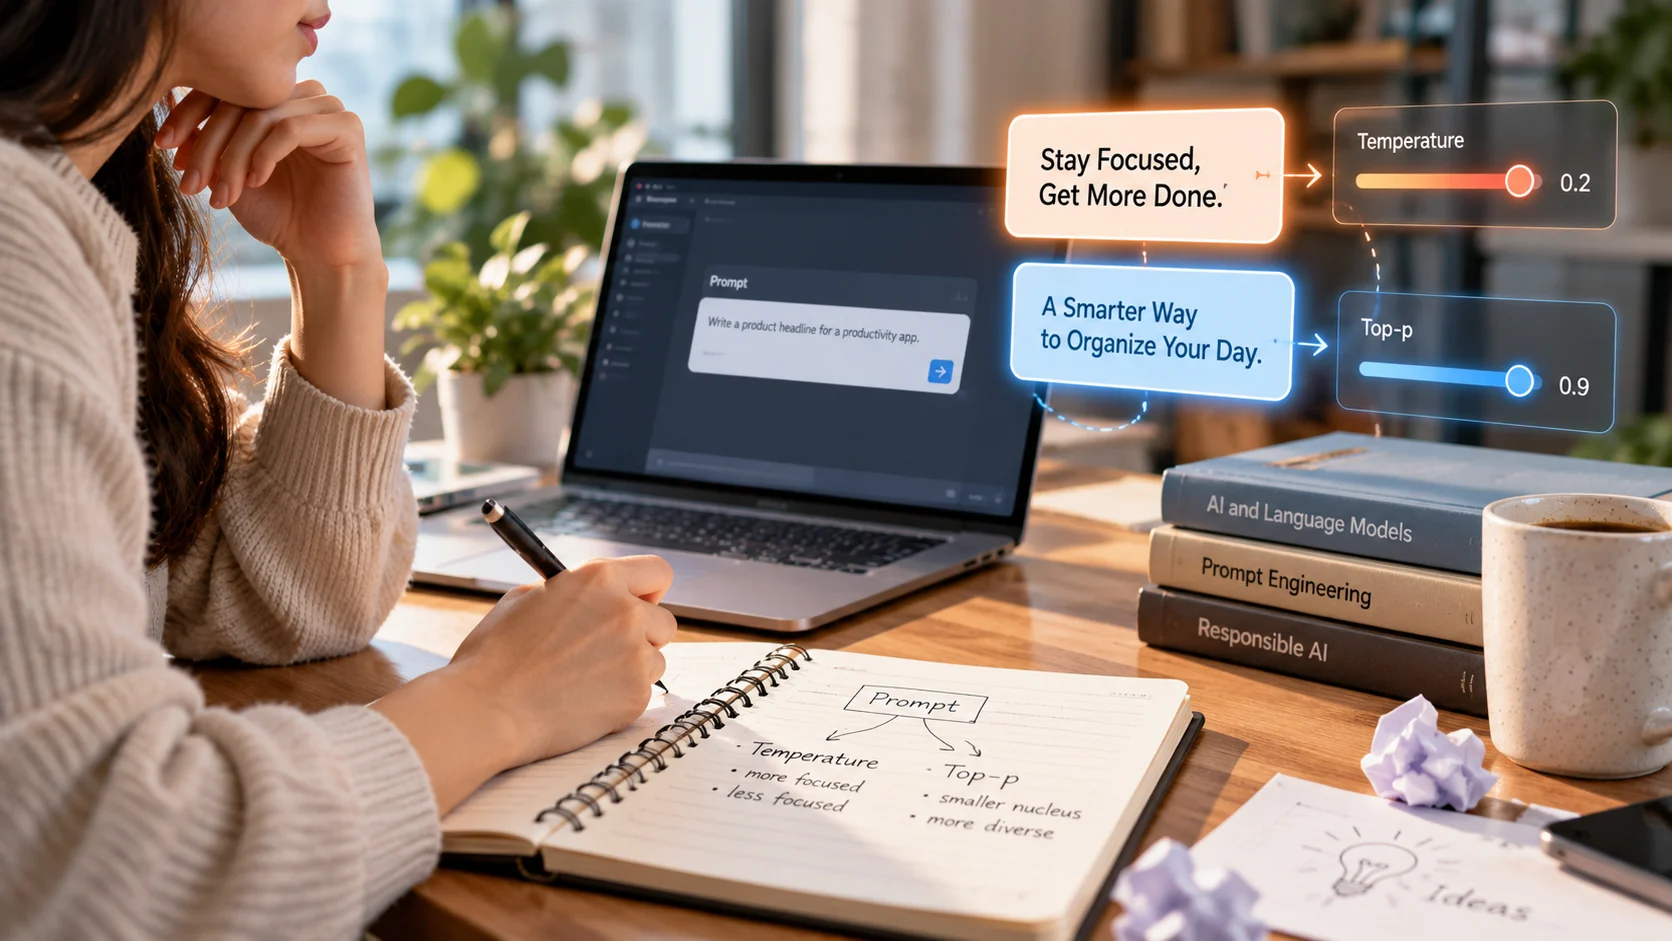
Temperature adjusts the relative probabilities of candidate tokens. In simplified terms, a lower positive temperature makes the model concentrate more strongly on high-scoring candidates; a higher temperature spreads probability more broadly and makes less likely candidates more competitive.
Consider a prompt ending with “The instructions should be …” If the model strongly prefers “clear,” a low temperature tends to reinforce that preference. At a higher temperature, alternatives such as “brief” or “concise” may appear more often. This can make outputs more varied, but it can also increase the chance of awkward or unsuitable wording.
The mathematical operation commonly divides token scores, or logits, by temperature before applying softmax. The resulting probability distribution is then used by the decoding algorithm. You do not need to calculate softmax to use the setting, but understanding the direction of its effect prevents the mistaken belief that temperature changes the model’s actual knowledge.
A value of zero is sometimes implemented through greedy or nearly greedy selection, but behavior depends on the service. It should not be treated as a universal guarantee that repeated requests will produce identical text.
Top-P: Restricting the Candidate Set
Top-p takes a different approach. Rather than reshaping the entire distribution alone, nucleus sampling keeps a dynamically sized group of high-probability tokens whose cumulative probability reaches a chosen threshold. The system then selects among that eligible group according to its sampling method.
For instance, a low top-p threshold can exclude unlikely continuations, while a higher threshold allows more of the probability tail to remain available. Unlike choosing a fixed number of candidates, the size of the nucleus changes from one generation step to the next. A very confident distribution may need only a few candidates; a flatter distribution may admit many.
Temperature and top-p are not opposing switches. They can both be applied during generation and therefore interact. Adjusting them simultaneously makes it harder to determine which control caused the observed difference. Some provider documentation explicitly recommends tuning one at a time.
Worked Example: Four Candidate Tokens
Imagine an invented distribution for the next token:
Candidate token Illustrative probability Cumulative probability
clear 0.60 0.60
brief 0.25 0.85
concise 0.10 0.95
short 0.05 1.00
At temperature 1, assume those are the starting probabilities. A lower temperature would push more mass toward “clear.” A higher temperature would make the lower-ranked alternatives relatively more likely. If top-p were 0.80, the eligible nucleus would contain “clear” and “brief,” because their cumulative probability first crosses the threshold at 0.85. Those probabilities would then be renormalized within the eligible set.
This is a teaching example, not an observed output from any particular model. Real models evaluate much larger vocabularies and may use additional decoding controls. Still, the principle is the same: temperature reshapes preference; top-p restricts the candidates considered during sampling.
How Temperature and Top-P Affect Different Tasks
Extracting product attributes
Suppose you need a model to read a product description and return size, color, material, and price in JSON. Useful variation is limited. The output should be consistent, structurally valid, and traceable to the source. A more restrictive sampling configuration may help reduce wording variability, but schema validation and checks against the source are still essential.
A low temperature cannot tell you whether the page actually stated a material. If the source is incomplete, the correct answer may be an explicit unknown value. Accuracy comes primarily from task design, source quality, and verification—not the temperature control.
Drafting customer-support responses
For support work, consistency of policy matters more than novelty. Different wording may be acceptable as long as delivery dates, refund rules, and instructions remain grounded in approved information. Test responses with ambiguous and outdated source documents, not just an easy question whose answer is obvious.
If a support model produces incorrect policy details, changing top-p is not a complete remedy. The underlying information retrieval, permission boundaries, or escalation process may need improvement.
Brainstorming headlines or campaign ideas
Idea generation may benefit from a broader range of phrasing. An exploratory configuration can increase variation, but the goal is useful variation, not randomness for its own sake. A batch of ten near-identical headlines is disappointing; a batch of ten wildly unrelated ones is not much better.
Judge diversity against practical constraints: brand voice, length, audience, clarity, factual claims, and originality within the supplied material. A human editor should reject catchy lines that imply benefits the product cannot deliver.
Producing structured reports
Reports often contain both factual and creative components. The data fields should be fixed and validated, while explanatory summaries may allow limited stylistic flexibility. If a workflow separates these stages, developers can apply different settings or methods to each. Trying to use one sampling configuration for every stage is convenient but not always effective.
A Controlled Experiment You Can Run
Start with five to ten prompts representative of the work you actually perform. Include a straightforward task, an incomplete input, a conflicting source, a longer task, and at least one example that previously caused an error. Record the model version and the precise prompt, including system instructions where applicable.
Next, establish a baseline. Run each prompt multiple times with the current settings and record the outputs. For a structured task, count schema failures, missing fields, incorrect extractions, and unsupported facts. For creative writing, use a small human rubric assessing relevance, useful novelty, readability, and adherence to brand constraints.
Change only temperature and repeat the same prompts. Do not simultaneously alter the model, top-p, instructions, or reference documents. Then return temperature to the baseline and vary top-p if the provider supports it. Use repeated samples because one attractive output can create a misleading impression about typical performance.
Finally, choose a configuration that meets the task’s acceptance criteria, not the one producing the most entertaining demonstration. Save the settings and the known failure modes alongside the workflow. Retest when the model, prompt, or surrounding tools change.
A Simple Evaluation Table
A small team can organize its observations without sophisticated tooling:
Evaluation dimension Extraction task Brainstorming task
Correctness Exact field agreement with the source No invented product claims
Format Valid schema and required fields Headline length and style constraints
Variation Consistency is often desirable Distinct useful ideas are desirable
Failure review Missing and ambiguous source values Repetition, irrelevance, and awkward phrasing
Human judgment Verify critical fields Assess usefulness and tone
The table makes an important distinction: there is no universally correct level of randomness. A successful configuration depends on the job being done and the consequences of a wrong result.
Four Mistakes to Avoid
Treating temperature zero as a guarantee. Identical requests may still differ because of model updates, infrastructure details, changing tool responses, or provider implementation. When exact reproducibility matters, investigate the service’s documented options and record the complete test environment.
Turning up temperature to fix missing knowledge. More varied wording does not supply a missing product specification or an authoritative source. For factual work, use retrieval, a verified database, or explicit uncertainty handling.
Changing temperature and top-p together. This obscures the cause of any improvement or deterioration. A controlled experiment is slower than randomly adjusting two sliders, but it generates evidence you can act upon.
Evaluating only one answer. Sampling settings affect distributions of outputs. One successful example cannot tell you how often the same configuration produces repetition, malformed data, or unsupported claims. Use multiple runs across representative prompts.
Reproducibility, Seeds, and Model Versions
Some APIs expose a random seed or other controls intended to make repeated generation more consistent. A seed is useful for experiments, but it should be interpreted according to the provider’s documentation. It does not make outputs permanently identical across changes to a model, service configuration, or tool context.
For durable internal evaluations, store the prompt, model identifier, any model-version details provided, sampling parameters, seed when supported, tools used, reference documents, and evaluation date. If a later run changes, the team can then investigate the difference rather than relying on memory of the previous test.
This is particularly important for business automation. Consistency in a demonstration is less valuable than knowing why output behavior changed after a deployment.
Choosing a Starting Configuration Without False Precision
There is no reliable universal table that says every factual task should use one exact temperature and every creative task another. Providers can differ in model behavior, accepted parameter ranges, defaults, and support for sampling controls. Some model interfaces may not expose temperature or top-p at all. That is a product constraint, not a reason to force a particular setting into the workflow.
For a task that must produce machine-readable data, begin by defining the schema and an independent validator. Use the provider’s supported structured-output features when appropriate. Then test whether changes to sampling affect the frequency of invalid fields, unsupported information, or inconsistent extraction. It is entirely possible to obtain perfectly valid JSON containing incorrect facts; that failure deserves a separate metric.
For a writing task, describe the difference between variety and quality before testing. A new headline should offer a genuinely different angle, not simply replace one adjective with a synonym. Editors can tag outputs by concept, identify repeated structures, and record how many suggestions are usable without extensive rewriting. This approach produces more meaningful evidence than ranking generations by how surprising they sound.
For a useful record of the experiment, include the number of runs, the dates, and representative failed outputs—not only the best example. Document whether evaluators knew which settings produced each answer; otherwise personal expectations about high or low temperature can influence ratings. Whenever possible, use the same grading rubric for every candidate output. Keep the evaluation questions stable so a future reviewer can understand what was compared.
Finally, remember that a generation parameter is only one part of the application. A changed system instruction, retrieval result, or content policy can alter the response even when temperature and top-p remain untouched. When you observe a quality change, inspect the full workflow rather than assuming the sampling control is responsible.
Frequently Asked Questions
Does higher temperature make an AI model smarter?
No. Temperature affects token selection during generation. It does not increase the model’s training, factual knowledge, or underlying reasoning capability.
Should I use a low temperature for factual answers?
A restrictive setting may support consistency, but verified sources, clear instructions, and independent checks matter much more for factual accuracy. A confidently incorrect output can occur at low temperature.
Can top-p replace temperature?
Both influence sampling, but in different ways. Providers vary in how they implement and expose the controls. Test the setting that your chosen model supports rather than assuming the parameters behave identically everywhere.
Why do identical prompts sometimes produce identical responses anyway?
The probability distribution may strongly favor the same choices, or the application may use deterministic decoding. Repetition can occur even in a sampling-based system when one continuation is substantially more likely than alternatives.
Conclusion
Temperature and top-p are tools for controlling how a language model chooses its next tokens. Temperature changes how sharply alternatives are preferred, while top-p narrows the set of candidates available for sampling. Neither replaces prompt design, source verification, or task-specific evaluation. Choose settings through controlled tests, document the results, and remember that the best amount of variation depends on whether you need reliable extraction, clear communication, or genuinely useful ideas.
Further Reading on ByteScope
Prompt Engineering for Beginners
AI Hallucinations Explained
AI Model Parameters Explained
Sources and Further Reading
Hugging Face: Text Generation Strategies
Hugging Face: Generation Configuration
The examples describe decoding concepts rather than performance claims for a particular commercial service.