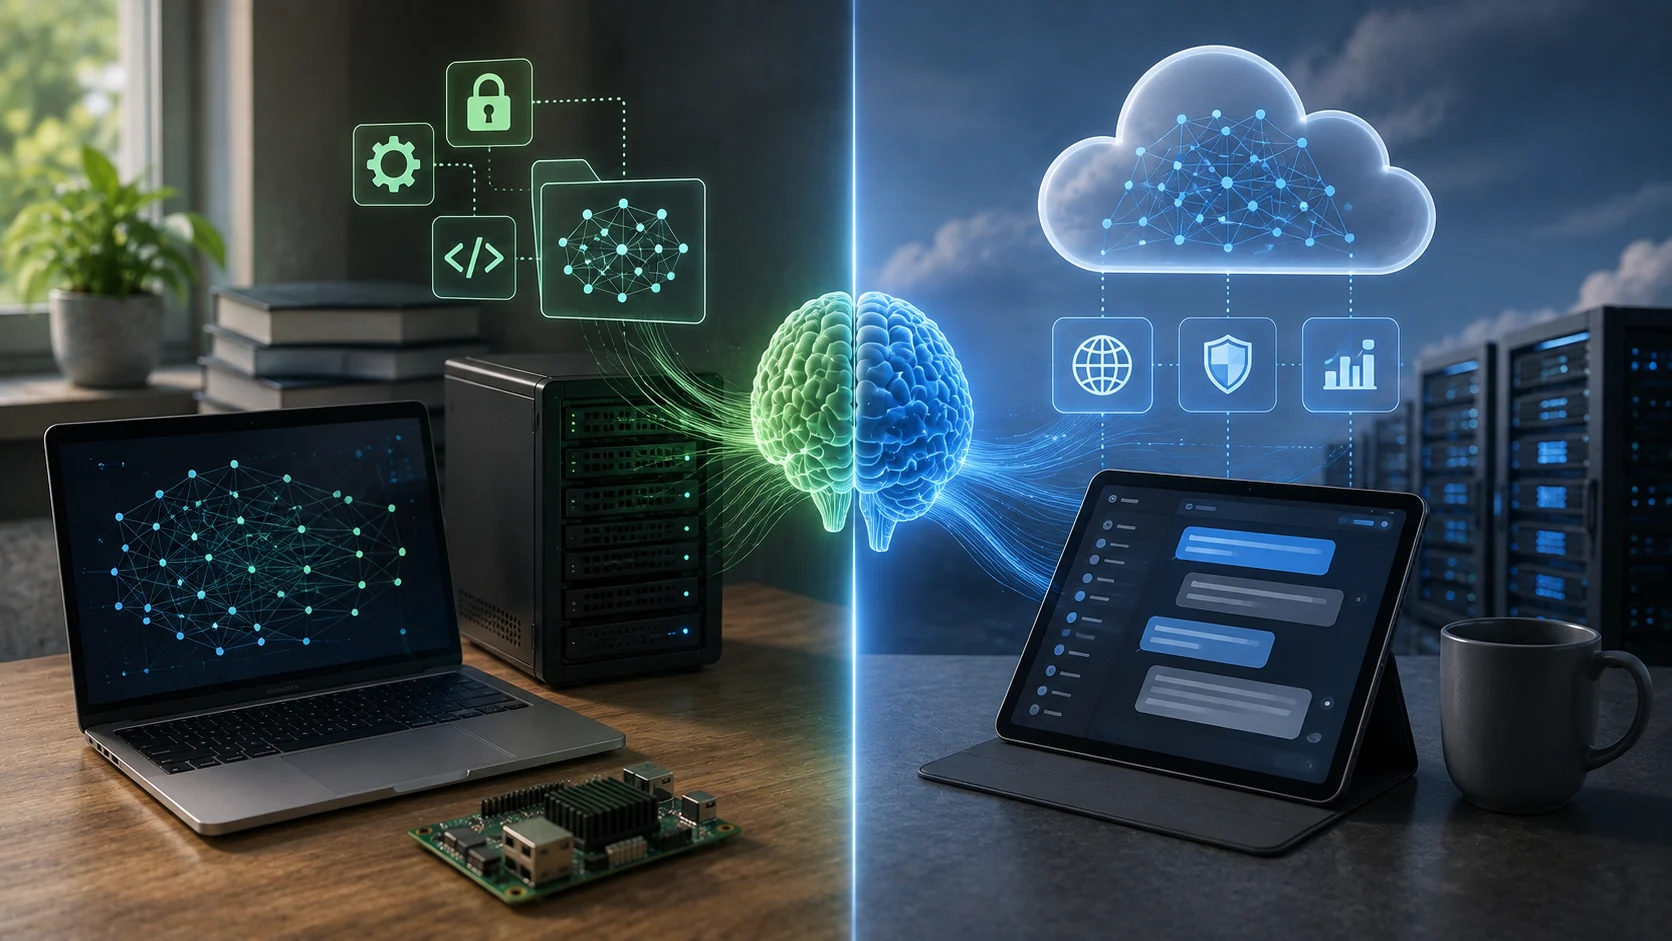
Developers choosing an AI model often encounter a basic strategic question: should the system use an open model that can be downloaded and deployed under its license, or a closed model accessed through a provider’s service? The answer affects control, cost, security, customization, and maintenance.
The phrase open-source AI is sometimes used loosely. Many models are more accurately described as open-weight because the model weights are available while the training data, full training code, or development process may not be completely open.
What Is an Open AI Model?
An open or open-weight model gives developers access to model weights under specified license terms. Depending on the project, developers may be able to download the model, run it on their own hardware, modify it, fine-tune it, and distribute derivatives.
The exact freedoms vary by license. “Open” should never be assumed to mean unlimited use.
What Is a Closed AI Model?
A closed model is typically provided as a managed service. Users send requests through an application or API, while the provider controls the weights, infrastructure, model updates, and much of the deployment environment.
This can simplify development because the customer does not need to manage model servers, acceleration hardware, scaling, or low-level inference optimization.
Control and Customization
Open models can provide greater control. Developers can choose where the model runs, apply quantization, fine-tune weights, inspect architecture details, or integrate the model into specialized infrastructure.
Closed services may offer customization through prompts, tools, retrieval, fine-tuning APIs, or configurable safety controls without exposing the underlying weights.
The right choice depends on how much low-level control the project actually needs.
Deployment and Privacy
An open model can sometimes run entirely inside an organization’s own environment. This may be valuable for sensitive workflows, offline systems, or strict data residency requirements.
A closed provider can also offer strong enterprise privacy and security controls, but the organization must evaluate the provider’s policies and architecture.
Self-hosting does not automatically guarantee privacy. The organization becomes responsible for securing the model, logs, infrastructure, and surrounding application.
Operational Complexity
Managed closed models reduce infrastructure burden. The provider handles serving, scaling, hardware, updates, and reliability.
Self-hosting an open model requires engineering work. Teams may need GPU infrastructure, monitoring, model optimization, security controls, backups, and deployment expertise.
This is a major reason a technically “free” model can still have meaningful operational cost.
Cost Is More Complicated Than API Price
Closed services often charge based on usage. This is convenient at low or unpredictable volume because there is little upfront infrastructure cost.
Open models may become attractive when usage is large, stable, or local hardware is already available. But hardware, engineering, electricity, and maintenance must be included in the calculation.
Transparency and Research
Open weights can help researchers inspect behavior, test modifications, reproduce experiments, and study model internals. This can accelerate innovation and education.
However, access to weights does not reveal every aspect of training. Important information about datasets, filtering, reinforcement learning, or evaluation may still be limited.
Transparency is therefore a spectrum rather than a simple open-versus-closed switch.
Safety and Responsibility
Closed providers can enforce centralized safety policies and update protections across all customers. Open deployment gives users more flexibility but also places more responsibility on the person or organization operating the model.
That responsibility includes misuse prevention, access control, evaluation, content policies, and monitoring. These considerations are part of responsible AI.
Open Models for Local AI
Open-weight model families are particularly useful for small language models and edge deployment. Developers can optimize models for specific devices and run them without continuous access to a provider’s cloud.
This can enable private assistants, embedded AI, research projects, and specialized enterprise systems.
Closed Models for Fast Product Development
Closed APIs can be a strong choice when a team wants advanced capabilities without managing infrastructure. A developer can prototype quickly, switch models through an API, and scale usage without operating a model cluster.
The tradeoff is dependence on the provider’s pricing, product roadmap, availability, and access rules.
How to Choose
Evaluate the real requirements: model quality, data sensitivity, latency, offline operation, customization, infrastructure skills, expected volume, licensing, support, and long-term portability.
Many organizations use both. A local open model can handle routine or sensitive work, while a hosted model handles difficult tasks that benefit from greater capability.
The Bottom Line
Open and closed AI models represent different operating models rather than a simple good-versus-bad choice. Open weights can provide control and deployment flexibility. Closed services can provide convenience, managed infrastructure, and rapid access to advanced capabilities.
The best strategy depends on the application’s constraints. Teams should compare the complete system cost and responsibility, not just the model download or API price.
A Practical Checklist Before You Rely on Open And Closed Ai Models
Define the job first. Decide what success means before choosing a model or product. A system can look impressive in a demo while solving the wrong problem. Write down the expected output, the information it may use, the acceptable error rate, and which decisions still require a person.
Test representative examples. A useful first test is to compare one self-hosted model and one managed API using the same workload, including engineering time and security requirements. Include normal cases and difficult edge cases. The goal is to learn where the system is dependable and where it needs stronger instructions, additional tools, or human review.
Verify important outputs. Do not confuse fluency with correctness. Check facts, calculations, citations, permissions, and important transformations against a reliable source. The more expensive or difficult an error would be to reverse, the stronger the verification process should be.
Review privacy and access. Understand what information is being sent to the system, where it is stored, and who can retrieve it later. Give connected AI tools only the permissions they need. Sensitive data should follow the same governance rules that apply elsewhere in the organization.
Measure value over time. Track time saved, correction rate, reliability, user satisfaction, and operational cost. A tool that feels fast during the first week may not create lasting value if people spend the same amount of time fixing its output.
Common Mistakes to Avoid
One common mistake is choosing technology before defining the workflow. Another is testing only ideal examples. Teams also tend to add automation without planning what happens when the model is uncertain, the data is missing, or a connected service fails.
The most important limitation to keep in mind is that license terms, operational burden, privacy, and vendor dependence can matter more than headline model quality. Build the workflow around that reality rather than assuming future model improvements will automatically solve it.
Frequently Asked Questions
Is open and closed AI models always more accurate than a simpler approach?
No. AI is valuable when the task benefits from language understanding, pattern recognition, generation, or flexible decision support. A deterministic rule, database query, spreadsheet formula, or conventional software function can be better when the task is predictable and exact.
Do I need to understand the mathematics behind open and closed AI models?
No. A conceptual understanding is enough for most users and product decisions. Mathematics becomes more important when you are implementing, optimizing, or researching open and closed AI models at a technical level. Start with the purpose, inputs, outputs, tradeoffs, and failure modes before going deeper into equations.
What is the safest way to start using open and closed AI models?
Begin with a narrow, reversible use case. Keep source material or original data available, review the output manually, and document the situations where the system fails. Expand automation only after the workflow performs consistently on representative examples and users know how to recover when it is wrong.