An AI assistant can sometimes appear to remember preferences, past conversations, or project details. That can make it feel as if the model has a human-like memory. In practice, AI memory is usually created by software around the model rather than by an unlimited memory inside the model itself.
Understanding this distinction helps explain why an assistant remembers some details but forgets others, why memory can be edited or deleted in some products, and why developers build separate storage and retrieval systems.
Language Models Are Often Stateless
A basic language model receives input and generates output. Once that request is finished, the model does not automatically retain a permanent record of the interaction.
To continue a conversation, the application sends relevant conversation history again. This creates continuity, but the model is responding to supplied context rather than recalling an experience from an internal personal memory.
Context Is Short-Term Working Information
The context window works somewhat like short-term working information. It contains the material the model can actively use during the current request.
Context is limited. A long conversation may exceed that limit, forcing the application to remove, summarize, or selectively retrieve earlier information.
This is why context and memory should not be treated as the same thing.
Long-Term Memory Uses External Storage
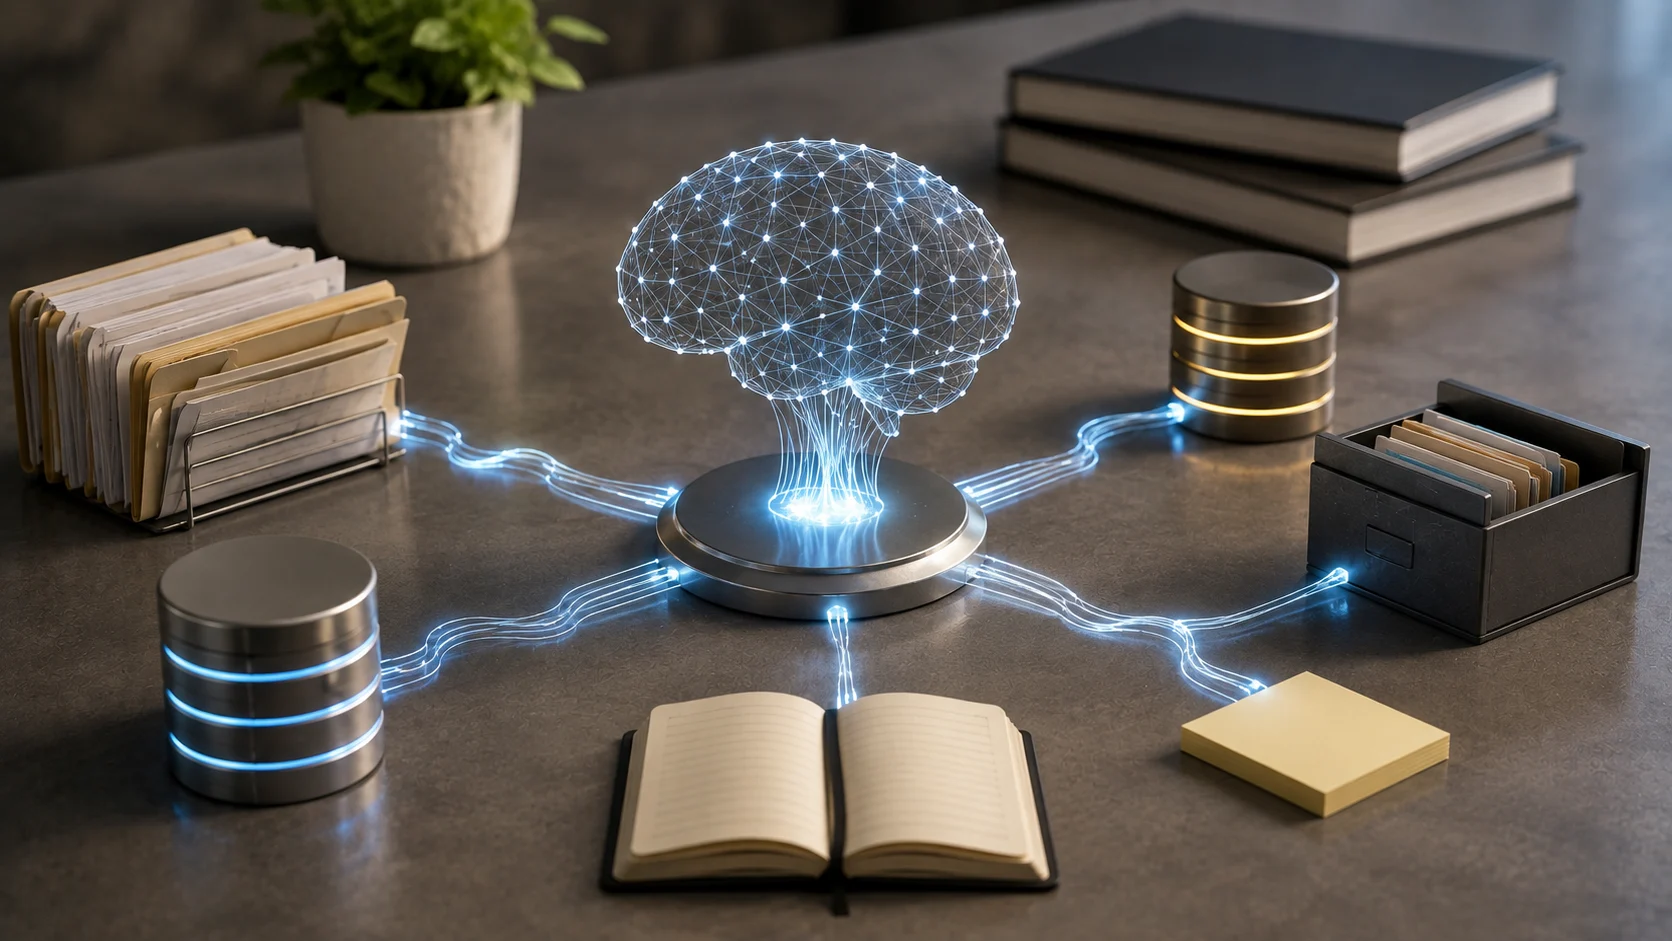
An application can store information outside the model in a database, document store, vector database, user profile, or another persistent system.
When the information becomes relevant later, the application retrieves it and places it back into the model’s context. The model then uses that retrieved memory like any other piece of input.
This architecture is similar to RAG, except the retrieved material may include personal or task-specific history rather than a general document library.
What Might an AI System Remember?
A memory system could store user preferences, project names, recurring instructions, facts about a workflow, previous decisions, task status, or summaries of earlier conversations.
The best memory systems are selective. Storing every sentence forever can create noise, privacy risk, and retrieval problems.
A useful system tries to identify information that is stable and likely to matter again.
Memory Retrieval Is a Ranking Problem
Saving information is only half the problem. The application must decide when to retrieve it.
One approach is semantic similarity using embeddings. A current request can be compared with stored memories, and the most relevant items are added to the prompt.
Other systems use explicit rules, timestamps, categories, user-selected facts, or a combination of methods.
Memory Can Become Outdated
People change preferences. Projects end. Policies are updated. A memory that was useful six months ago can become incorrect today.
Good memory systems therefore need mechanisms for editing, expiration, conflict resolution, and deletion. They should not silently treat old information as permanently true.
AI Memory and Privacy
Persistent memory creates obvious privacy considerations. A product that stores personal details should make it clear what is saved, how long it is retained, and how users can manage it.
Developers should minimize unnecessary data, secure memory stores, respect access controls, and avoid storing sensitive information unless the use case requires it.
This is part of broader responsible AI design.
Memory for AI Agents
Agents often need memory because they work across several steps or repeated tasks. An agent might remember what it already tried, which files were changed, which customer request is being handled, or what goal remains incomplete.
Without structured memory, an agent may repeat work or lose track of state. This is one reason agent systems often combine model context with external databases, logs, and task state.
Summaries as Compressed Memory
A long conversation can be compressed into a shorter summary. This saves context space while preserving important decisions and facts.
The weakness is that summarization is lossy. A detail omitted from the summary may be difficult to recover later unless the original conversation remains searchable.
Critical information should therefore be stored explicitly rather than relying only on an automatically generated summary.
Memory Is Not Proof of Understanding
An AI system may remember a fact and still use it incorrectly. Retrieval can return the wrong memory, or the model can misinterpret the information after it is retrieved.
Memory improves continuity, but it does not eliminate reasoning errors or hallucinations.
The Bottom Line
AI memory is usually a system for storing information outside the core model and retrieving it when needed. The model’s context window provides temporary working information, while external storage can create longer-term continuity.
Useful memory systems must decide what to save, when to retrieve it, when to forget it, and how to protect it. The goal is not unlimited memory. It is relevant memory that improves the task without creating unnecessary privacy or accuracy problems.
A Practical Checklist Before You Rely on Ai Memory
Define the job first. Decide what success means before choosing a model or product. A system can look impressive in a demo while solving the wrong problem. Write down the expected output, the information it may use, the acceptable error rate, and which decisions still require a person.
Test representative examples. A useful first test is to store one stable preference, one temporary project fact, and one outdated fact, then test whether the system retrieves and updates them appropriately. Include normal cases and difficult edge cases. The goal is to learn where the system is dependable and where it needs stronger instructions, additional tools, or human review.
Verify important outputs. Do not confuse fluency with correctness. Check facts, calculations, citations, permissions, and important transformations against a reliable source. The more expensive or difficult an error would be to reverse, the stronger the verification process should be.
Review privacy and access. Understand what information is being sent to the system, where it is stored, and who can retrieve it later. Give connected AI tools only the permissions they need. Sensitive data should follow the same governance rules that apply elsewhere in the organization.
Measure value over time. Track time saved, correction rate, reliability, user satisfaction, and operational cost. A tool that feels fast during the first week may not create lasting value if people spend the same amount of time fixing its output.
Common Mistakes to Avoid
One common mistake is choosing technology before defining the workflow. Another is testing only ideal examples. Teams also tend to add automation without planning what happens when the model is uncertain, the data is missing, or a connected service fails.
The most important limitation to keep in mind is that persistent memory can become stale, irrelevant, or privacy-sensitive if there is no clear deletion and update process. Build the workflow around that reality rather than assuming future model improvements will automatically solve it.
Frequently Asked Questions
Is AI memory always more accurate than a simpler approach?
No. AI is valuable when the task benefits from language understanding, pattern recognition, generation, or flexible decision support. A deterministic rule, database query, spreadsheet formula, or conventional software function can be better when the task is predictable and exact.
Do I need to understand the mathematics behind AI memory?
No. A conceptual understanding is enough for most users and product decisions. Mathematics becomes more important when you are implementing, optimizing, or researching AI memory at a technical level. Start with the purpose, inputs, outputs, tradeoffs, and failure modes before going deeper into equations.
What is the safest way to start using AI memory?
Begin with a narrow, reversible use case. Keep source material or original data available, review the output manually, and document the situations where the system fails. Expand automation only after the workflow performs consistently on representative examples and users know how to recover when it is wrong.