Computers work with numbers, but many useful AI tasks involve meaning. A search engine may need to recognize that “car repair” is related to “vehicle maintenance.” A recommendation system may need to identify similar products. A document assistant may need to find a passage that answers a question even when the wording is different.
Embeddings are numerical representations that make these kinds of relationships easier for machine learning systems to work with.
What Is an Embedding?
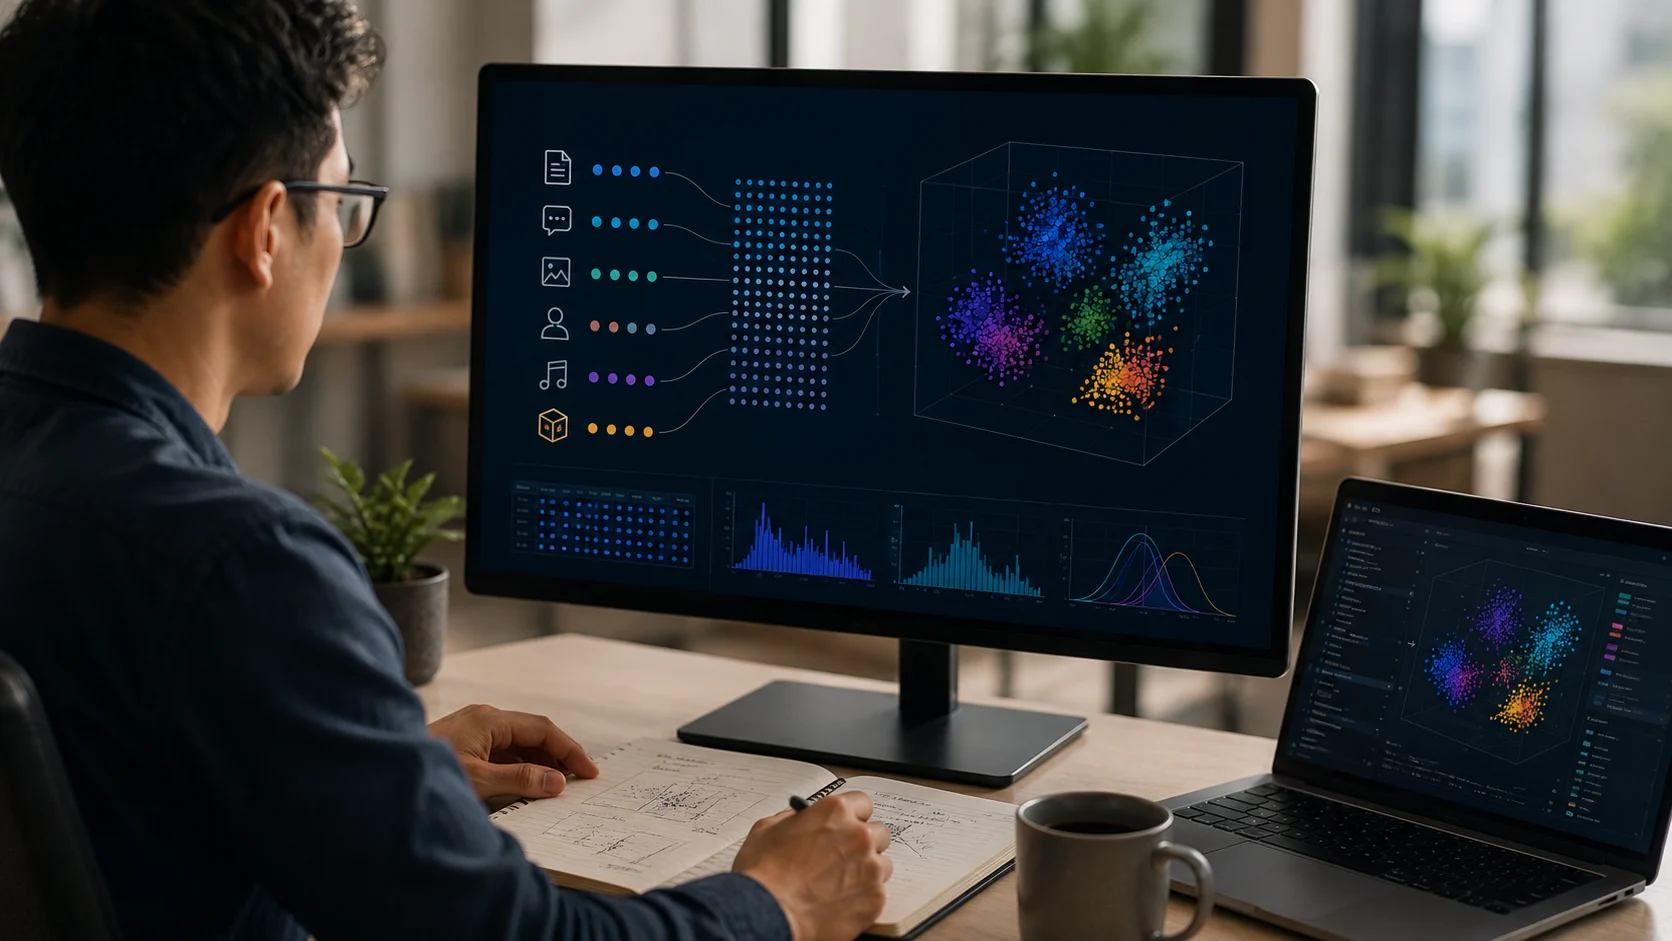
An embedding represents an item as a vector: an ordered list of numbers. The item might be a word, sentence, document, image, product, user, or another kind of data.
The important property is that the geometry of the vectors can capture useful relationships. Items with similar meaning or behavior may be positioned closer together in the embedding space than unrelated items.
This turns a fuzzy concept like semantic similarity into something a computer can compare mathematically.
Why Not Use Simple IDs?
A database can assign an ID to every item, but the ID itself contains no information about similarity. Product 104 is not automatically more related to product 105 than product 900.
Embeddings encode patterns learned from data. Two products with similar descriptions or user behavior may receive vectors that are close together even if their database IDs are unrelated.
What Does an Embedding Vector Look Like?
In real systems, an embedding may contain hundreds or thousands of numeric dimensions. Humans cannot directly visualize such a high-dimensional space, but the mathematical idea is similar to placing points on a map.
Distance or similarity functions can compare two vectors. A system can then retrieve the nearest items to a query vector.
Semantic Search
Semantic search is one of the most common uses of embeddings. A user’s question is converted into an embedding, and the system searches for document embeddings that are close to it.
This can find related passages without requiring an exact keyword match. The system may understand that “annual leave allowance” and “how many vacation days do I get?” are related concepts.
Embedding search is a major building block in Retrieval-Augmented Generation.
Embeddings for Recommendations
Recommendation systems can represent products, songs, articles, or users as vectors. Similar vectors can help identify items that share characteristics or behavior patterns.
For example, if two articles are frequently read by similar audiences and discuss related topics, their representations may end up close together in a learned embedding space.
Embeddings do not automatically produce a complete recommendation system, but they provide a useful representation for ranking and matching.
Clustering and Classification
Once items have embeddings, they can be grouped into clusters. A company might cluster customer feedback into themes, organize documents by topic, or identify groups of similar products.
Embeddings can also become features for classifiers. Instead of training a model directly on raw text, a system can classify the numerical representation.
Text Is Not the Only Data That Can Be Embedded
Images, audio, code, and other data can also be represented as embeddings. Multimodal systems may even map different modalities into related spaces.
This can enable tasks such as searching for an image using a text description or finding visually similar products. Our guide to multimodal AI explains the broader concept.
Embeddings Are Model-Dependent
There is no single universal embedding for a sentence. Different embedding models produce different vectors, dimensions, and similarity behavior.
An embedding model trained for general semantic similarity may not be ideal for specialized legal, medical, or product-search tasks. Developers should evaluate whether the representation works for their actual data.
Vector Databases
Large applications may store millions of embeddings. Searching every vector one by one would be inefficient, so specialized indexes and vector databases use approximate nearest-neighbor methods to find similar items quickly.
The database is only one part of the system. Document cleaning, chunking, embedding quality, metadata, and reranking can be equally important.
Privacy and Sensitive Data
An embedding is numerical, but it should not automatically be treated as anonymous. It is derived from source data and may preserve information useful for inference or reconstruction attacks depending on the model and system.
Organizations should apply appropriate access controls to embedding stores, especially when they represent private documents or user data.
The Bottom Line
Embeddings are dense numerical representations that help AI systems compare meaning and relationships. Similar concepts can be placed near each other in a vector space, making semantic search, recommendations, clustering, classification, and retrieval possible.
You rarely see embeddings directly as an everyday AI user, but they sit underneath many of the systems that help models find relevant information rather than relying only on exact words.
A Practical Checklist Before You Rely on Embeddings
Define the job first. Decide what success means before choosing a model or product. A system can look impressive in a demo while solving the wrong problem. Write down the expected output, the information it may use, the acceptable error rate, and which decisions still require a person.
Test representative examples. A useful first test is to test semantic search with queries that use different wording from the documents they should retrieve. Include normal cases and difficult edge cases. The goal is to learn where the system is dependable and where it needs stronger instructions, additional tools, or human review.
Verify important outputs. Do not confuse fluency with correctness. Check facts, calculations, citations, permissions, and important transformations against a reliable source. The more expensive or difficult an error would be to reverse, the stronger the verification process should be.
Review privacy and access. Understand what information is being sent to the system, where it is stored, and who can retrieve it later. Give connected AI tools only the permissions they need. Sensitive data should follow the same governance rules that apply elsewhere in the organization.
Measure value over time. Track time saved, correction rate, reliability, user satisfaction, and operational cost. A tool that feels fast during the first week may not create lasting value if people spend the same amount of time fixing its output.
Common Mistakes to Avoid
One common mistake is choosing technology before defining the workflow. Another is testing only ideal examples. Teams also tend to add automation without planning what happens when the model is uncertain, the data is missing, or a connected service fails.
The most important limitation to keep in mind is that vector similarity is useful but it does not prove that two items are equivalent or that the retrieved item is correct. Build the workflow around that reality rather than assuming future model improvements will automatically solve it.
Frequently Asked Questions
Is embeddings always more accurate than a simpler approach?
No. AI is valuable when the task benefits from language understanding, pattern recognition, generation, or flexible decision support. A deterministic rule, database query, spreadsheet formula, or conventional software function can be better when the task is predictable and exact.
Do I need to understand the mathematics behind embeddings?
No. A conceptual understanding is enough for most users and product decisions. Mathematics becomes more important when you are implementing, optimizing, or researching embeddings at a technical level. Start with the purpose, inputs, outputs, tradeoffs, and failure modes before going deeper into equations.
What is the safest way to start using embeddings?
Begin with a narrow, reversible use case. Keep source material or original data available, review the output manually, and document the situations where the system fails. Expand automation only after the workflow performs consistently on representative examples and users know how to recover when it is wrong.